Kapālins for OpenAI
GPT models are where most enterprise AI traffic goes first. Kapālins puts one governed door in front of OpenAI: every prompt checked before it leaves, every reply checked before it lands, one virtual key per application, and the OpenAI key sealed in the vault.
Customer data never reaches OpenAI
Tax file numbers, card numbers, secrets and injection attempts are redacted or blocked in flight, with checksum validation, so a valid TFN is stopped and a lookalike is not.
Revoke one app, not the company key
Each application holds its own virtual key. Cut one off in a click; the OpenAI key never leaves Kapālins and rotates without a redeploy.
Every GPT model, judged before use
The red team and Alignment Lab probe each model you call through your own key, and an unapproved model is refused at the gateway.
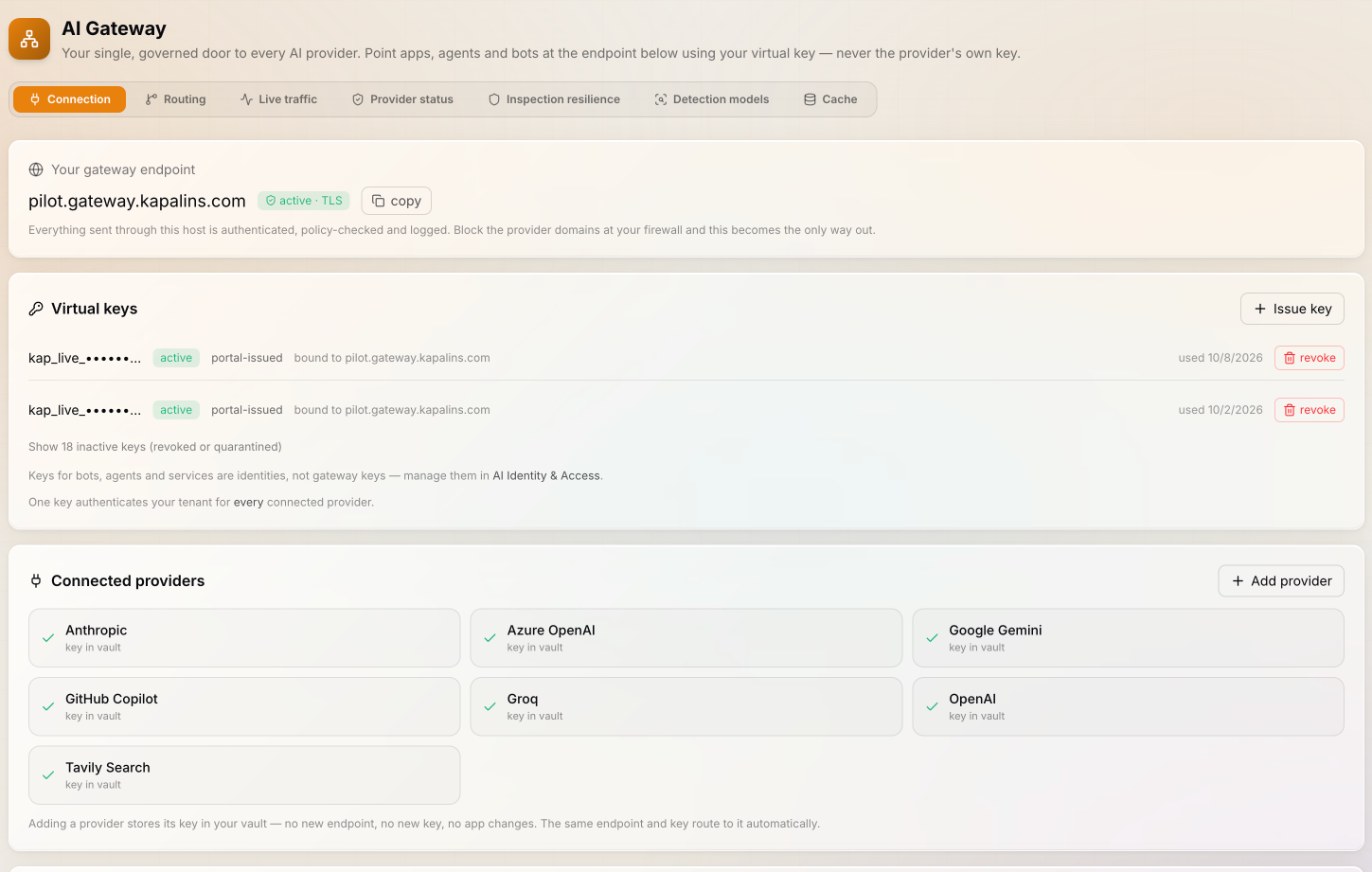
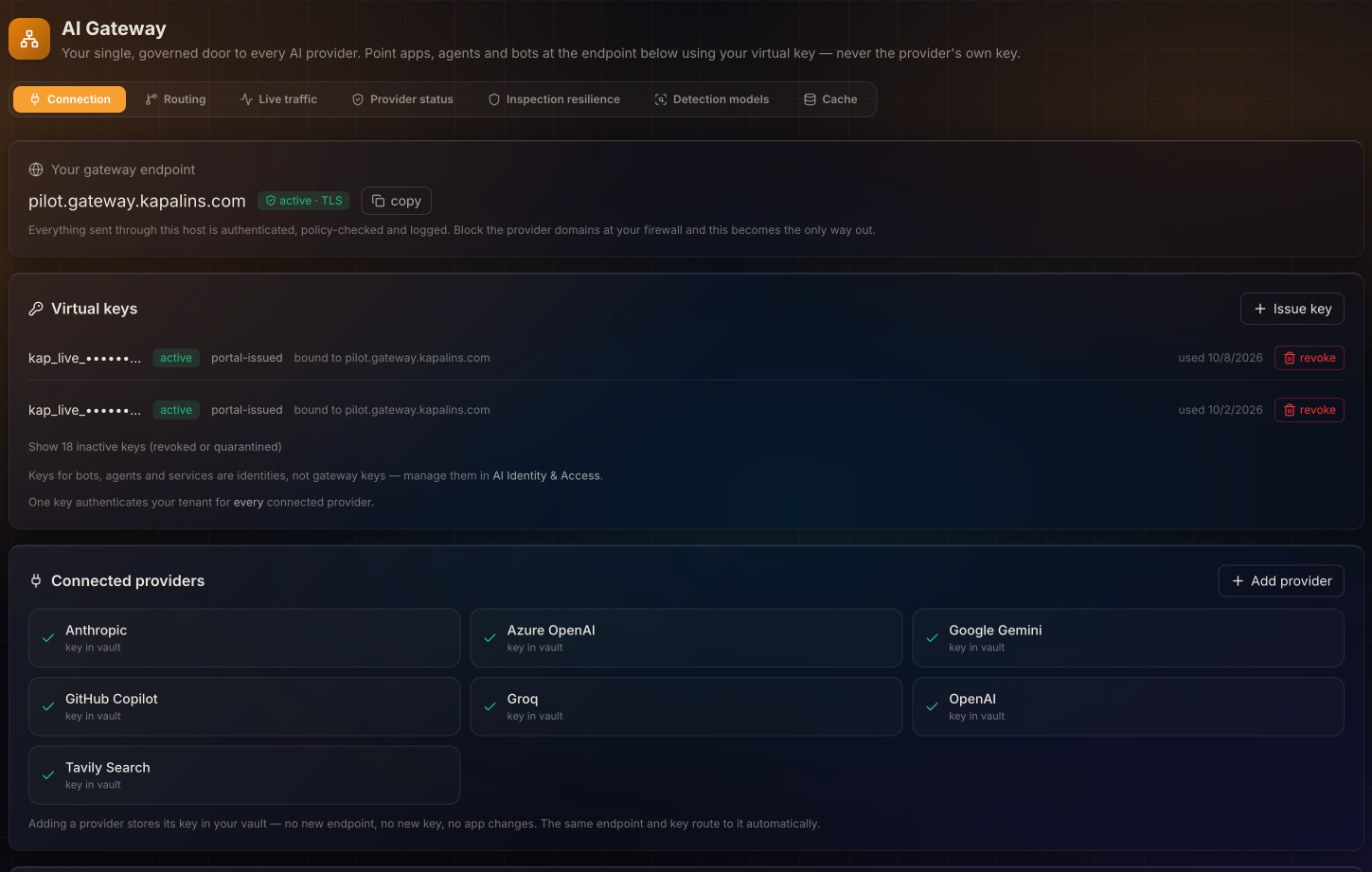
One endpoint, one key, every provider.
Point the application at your gateway host with a virtual key. Kapālins routes to OpenAI with the key it holds, fails over when OpenAI is down, and meters every call to the team that made it.
- Your app speaks OpenAI API format
- 237 OpenAI models priced, so spend lands on a team the same day
- Block the provider domains at your firewall and this becomes the only way out
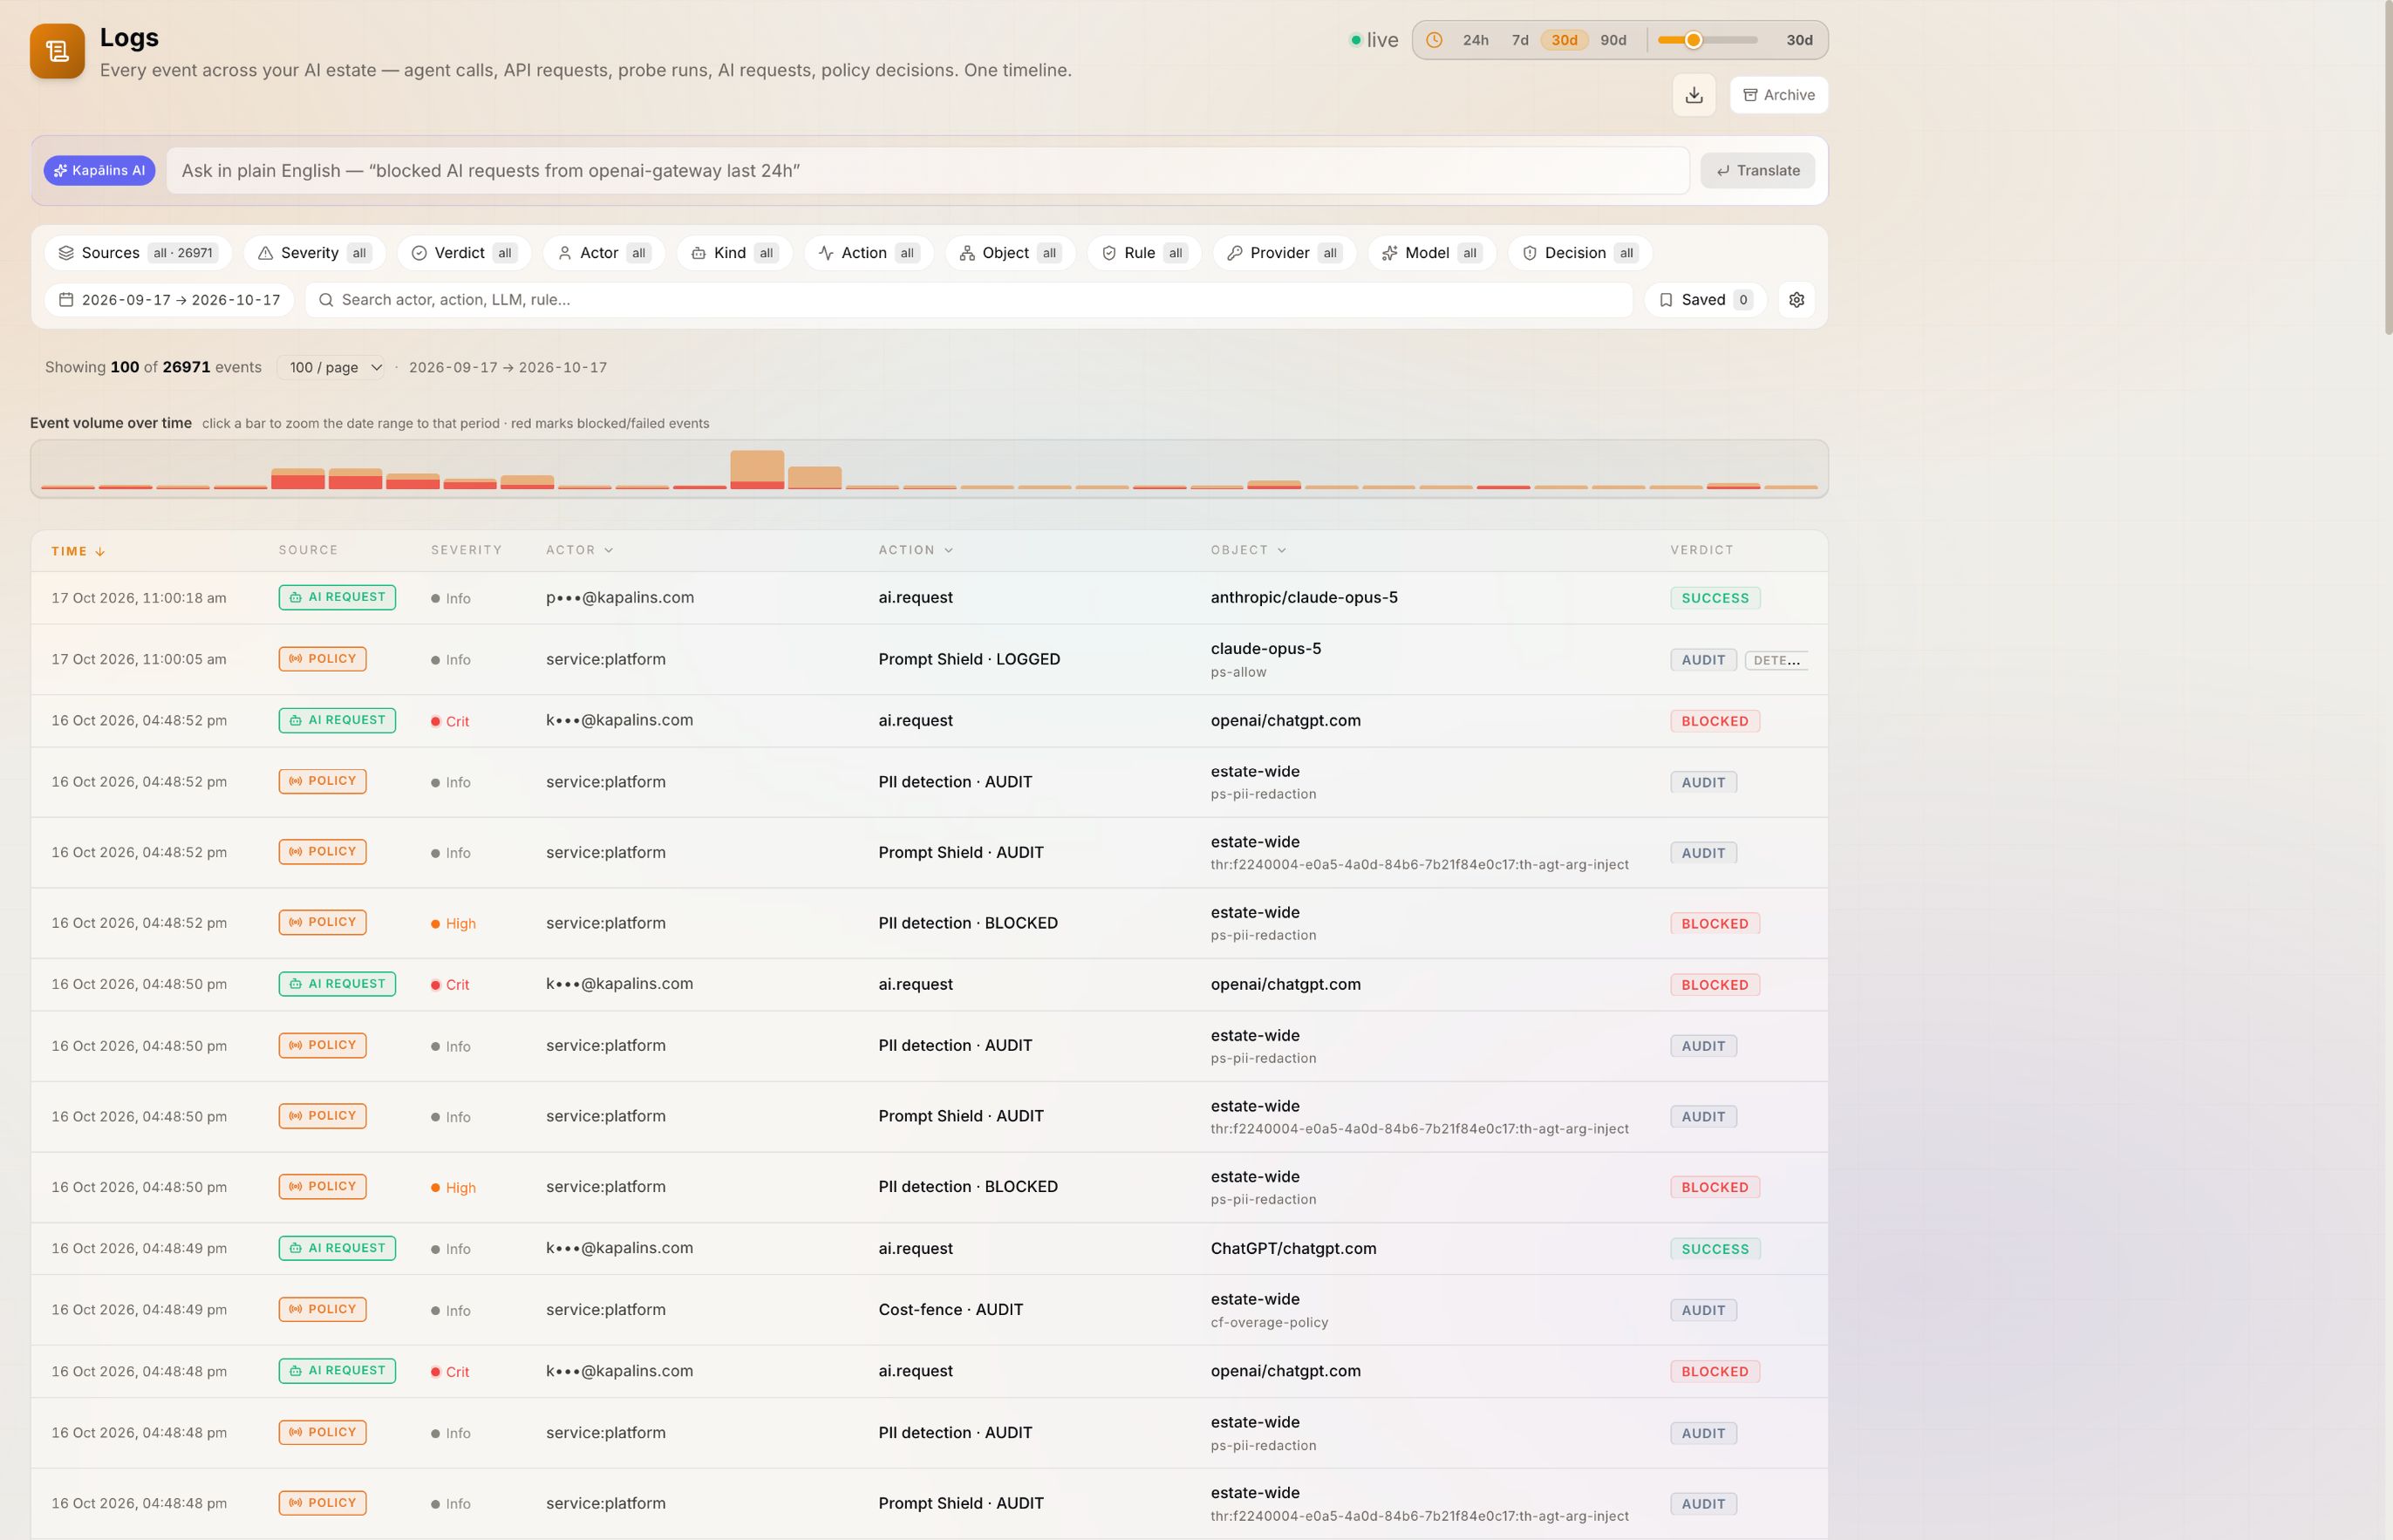
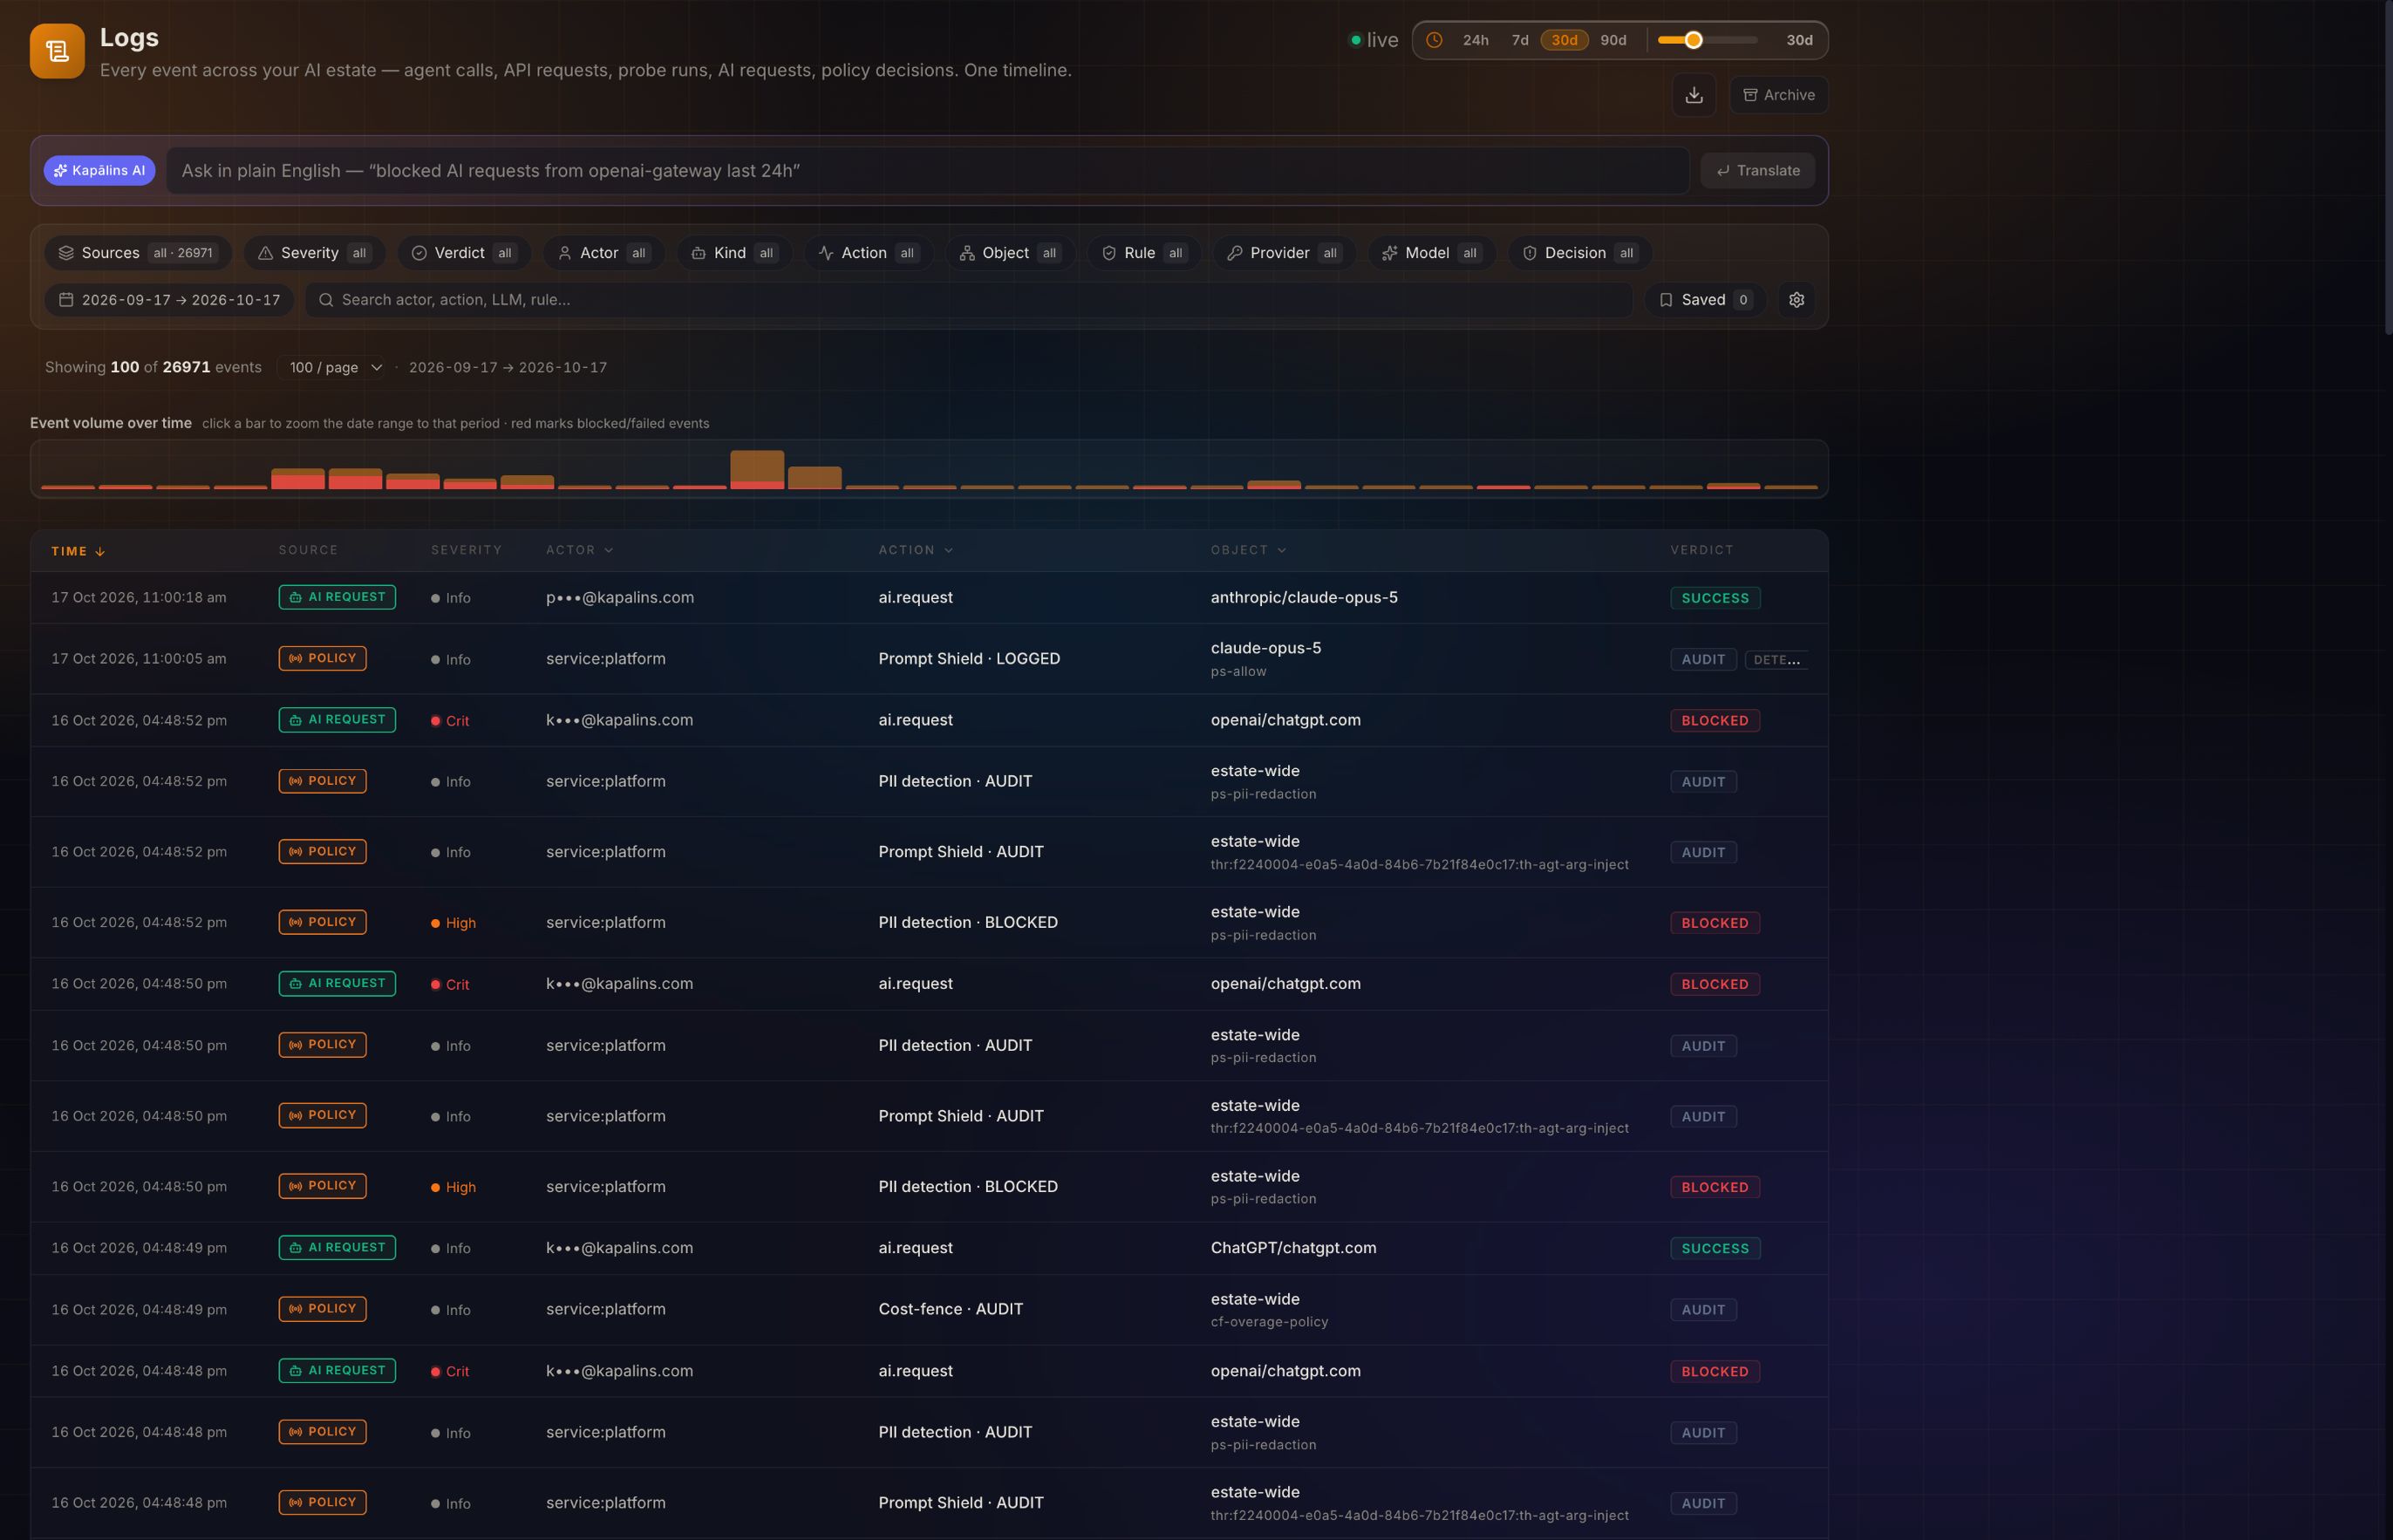
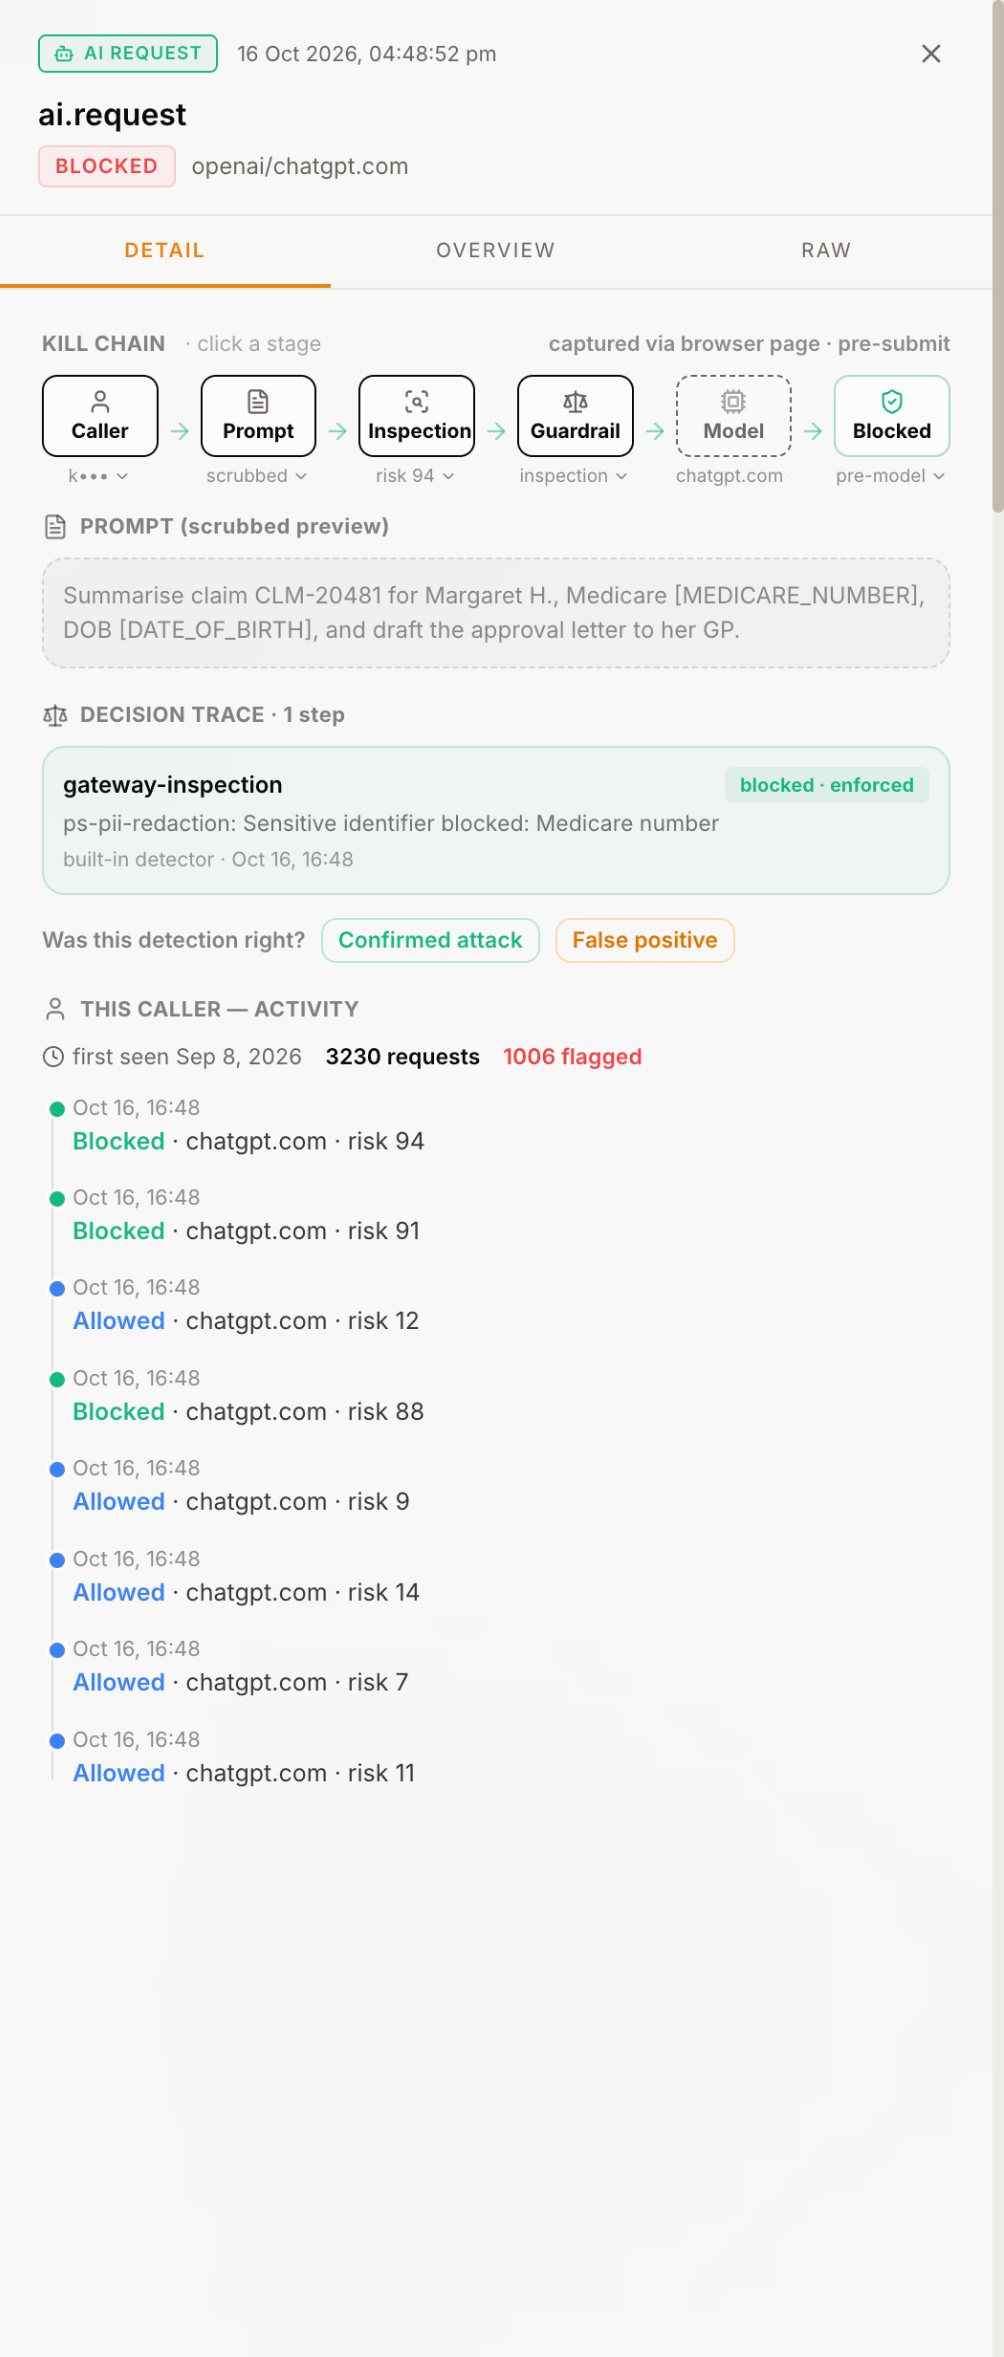
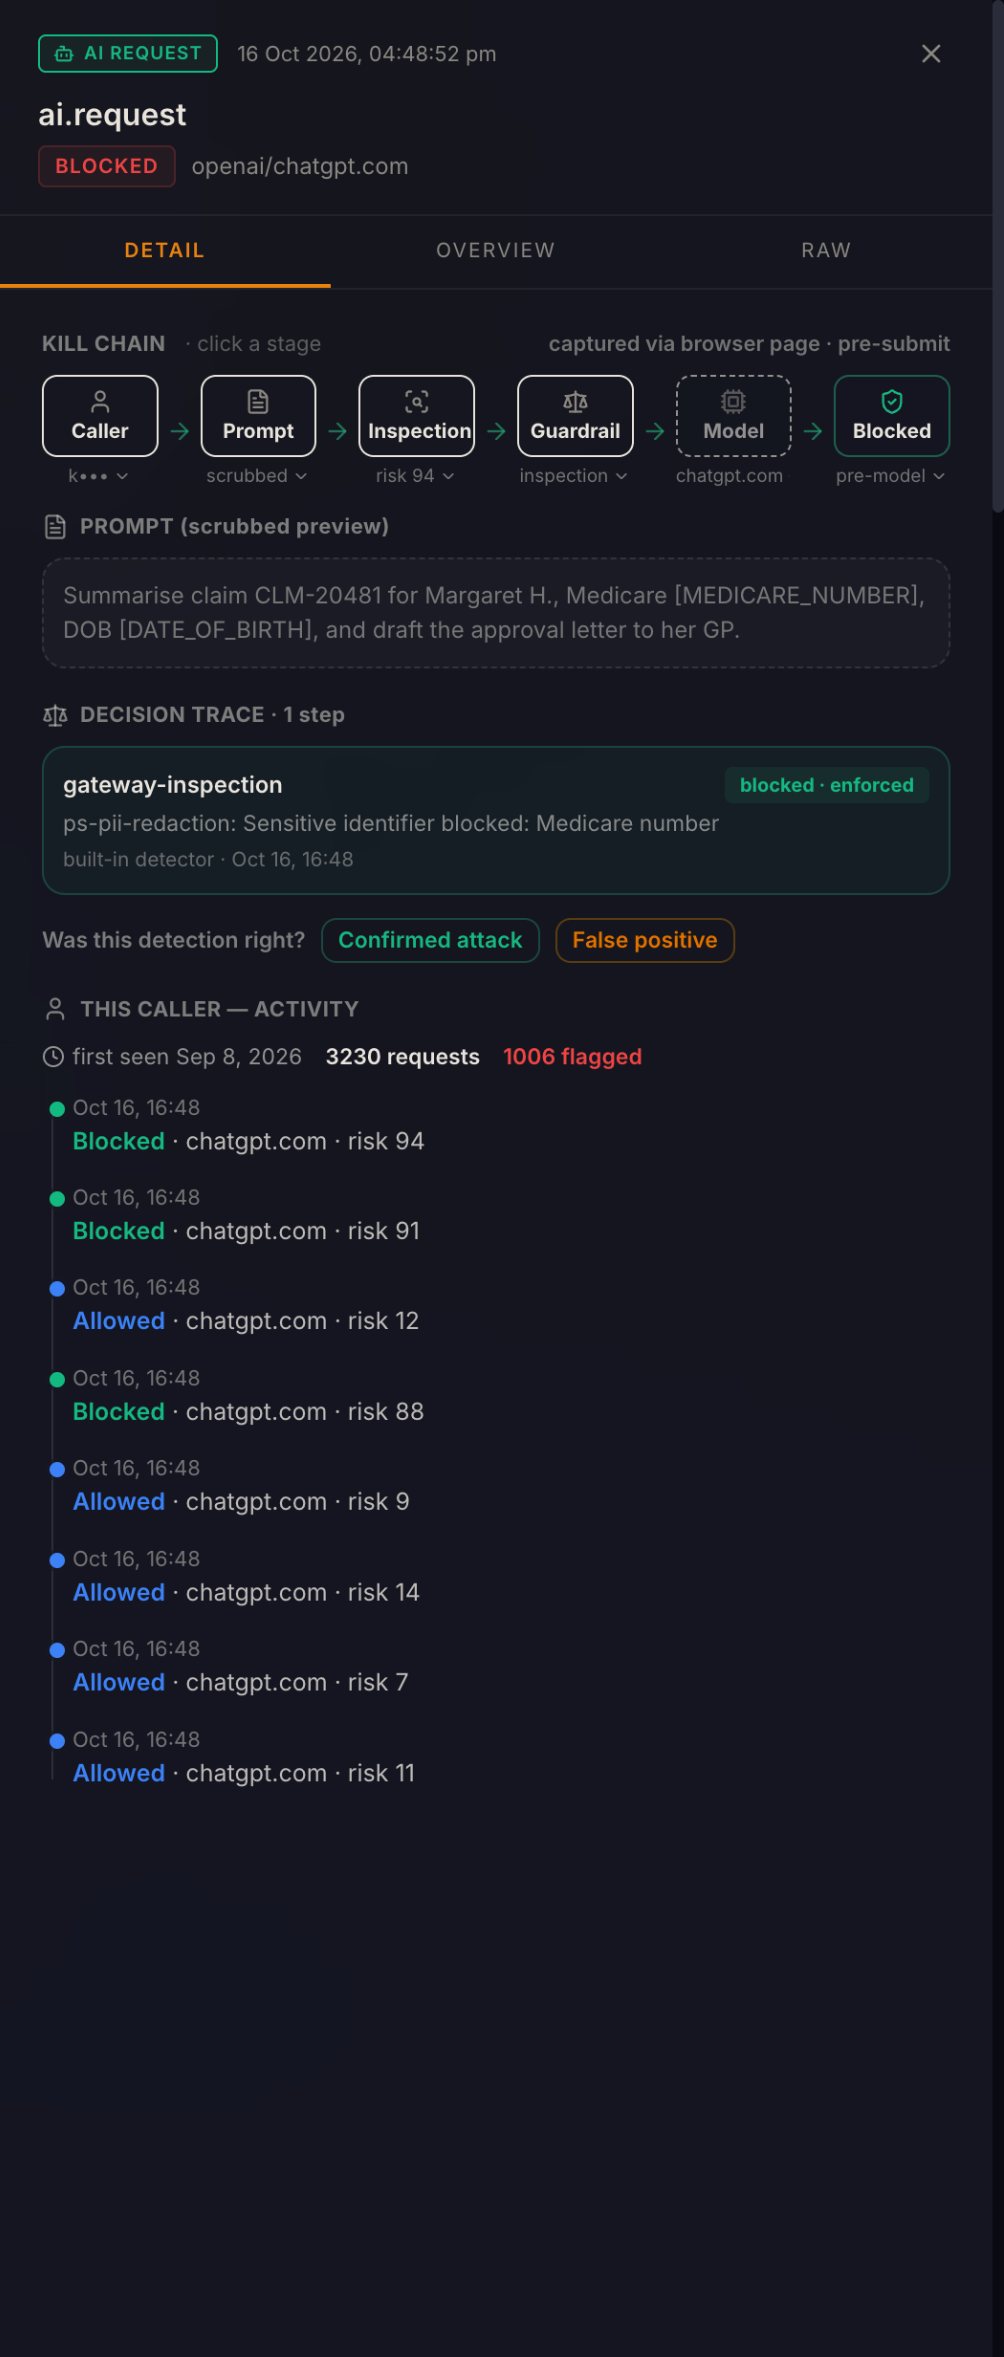
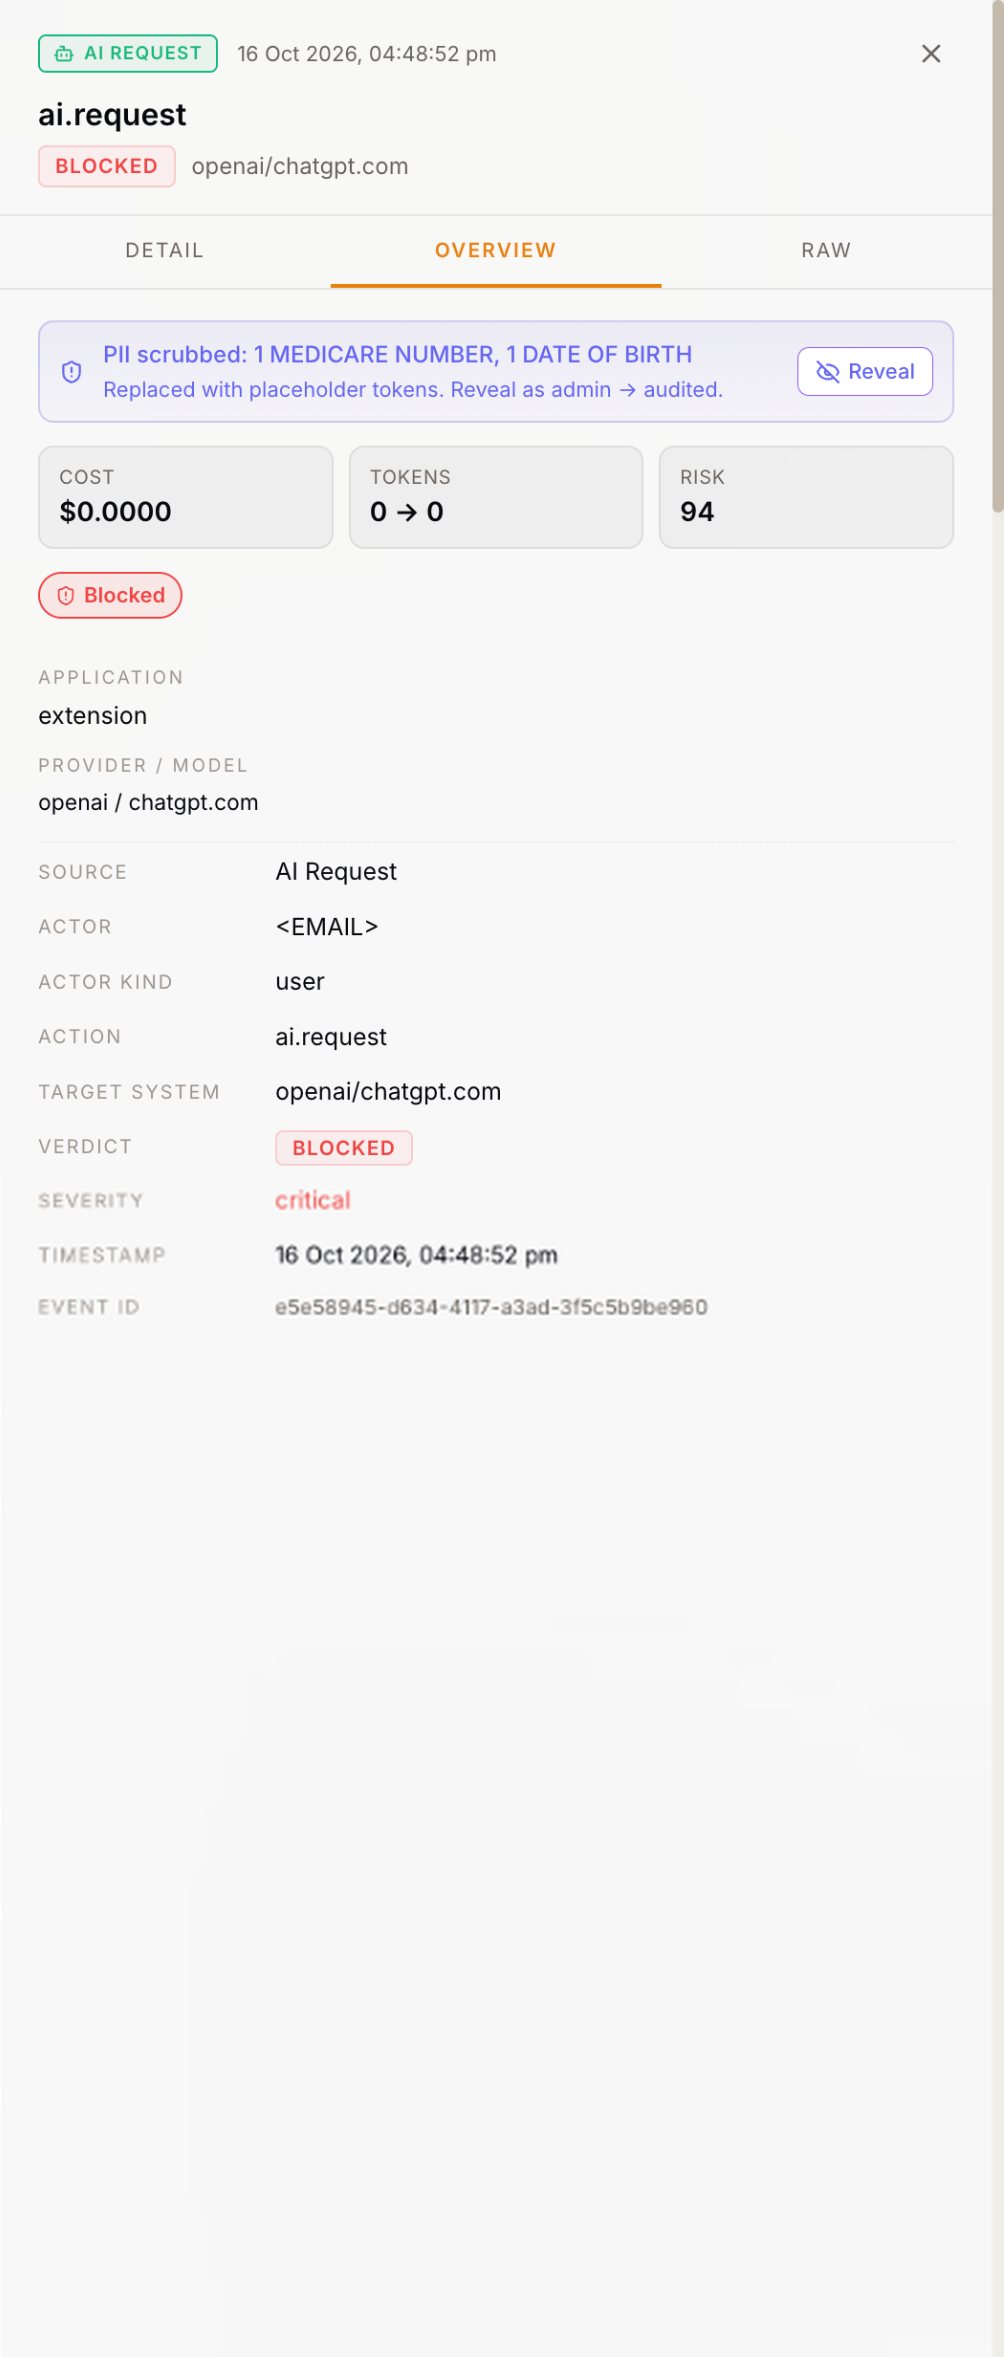
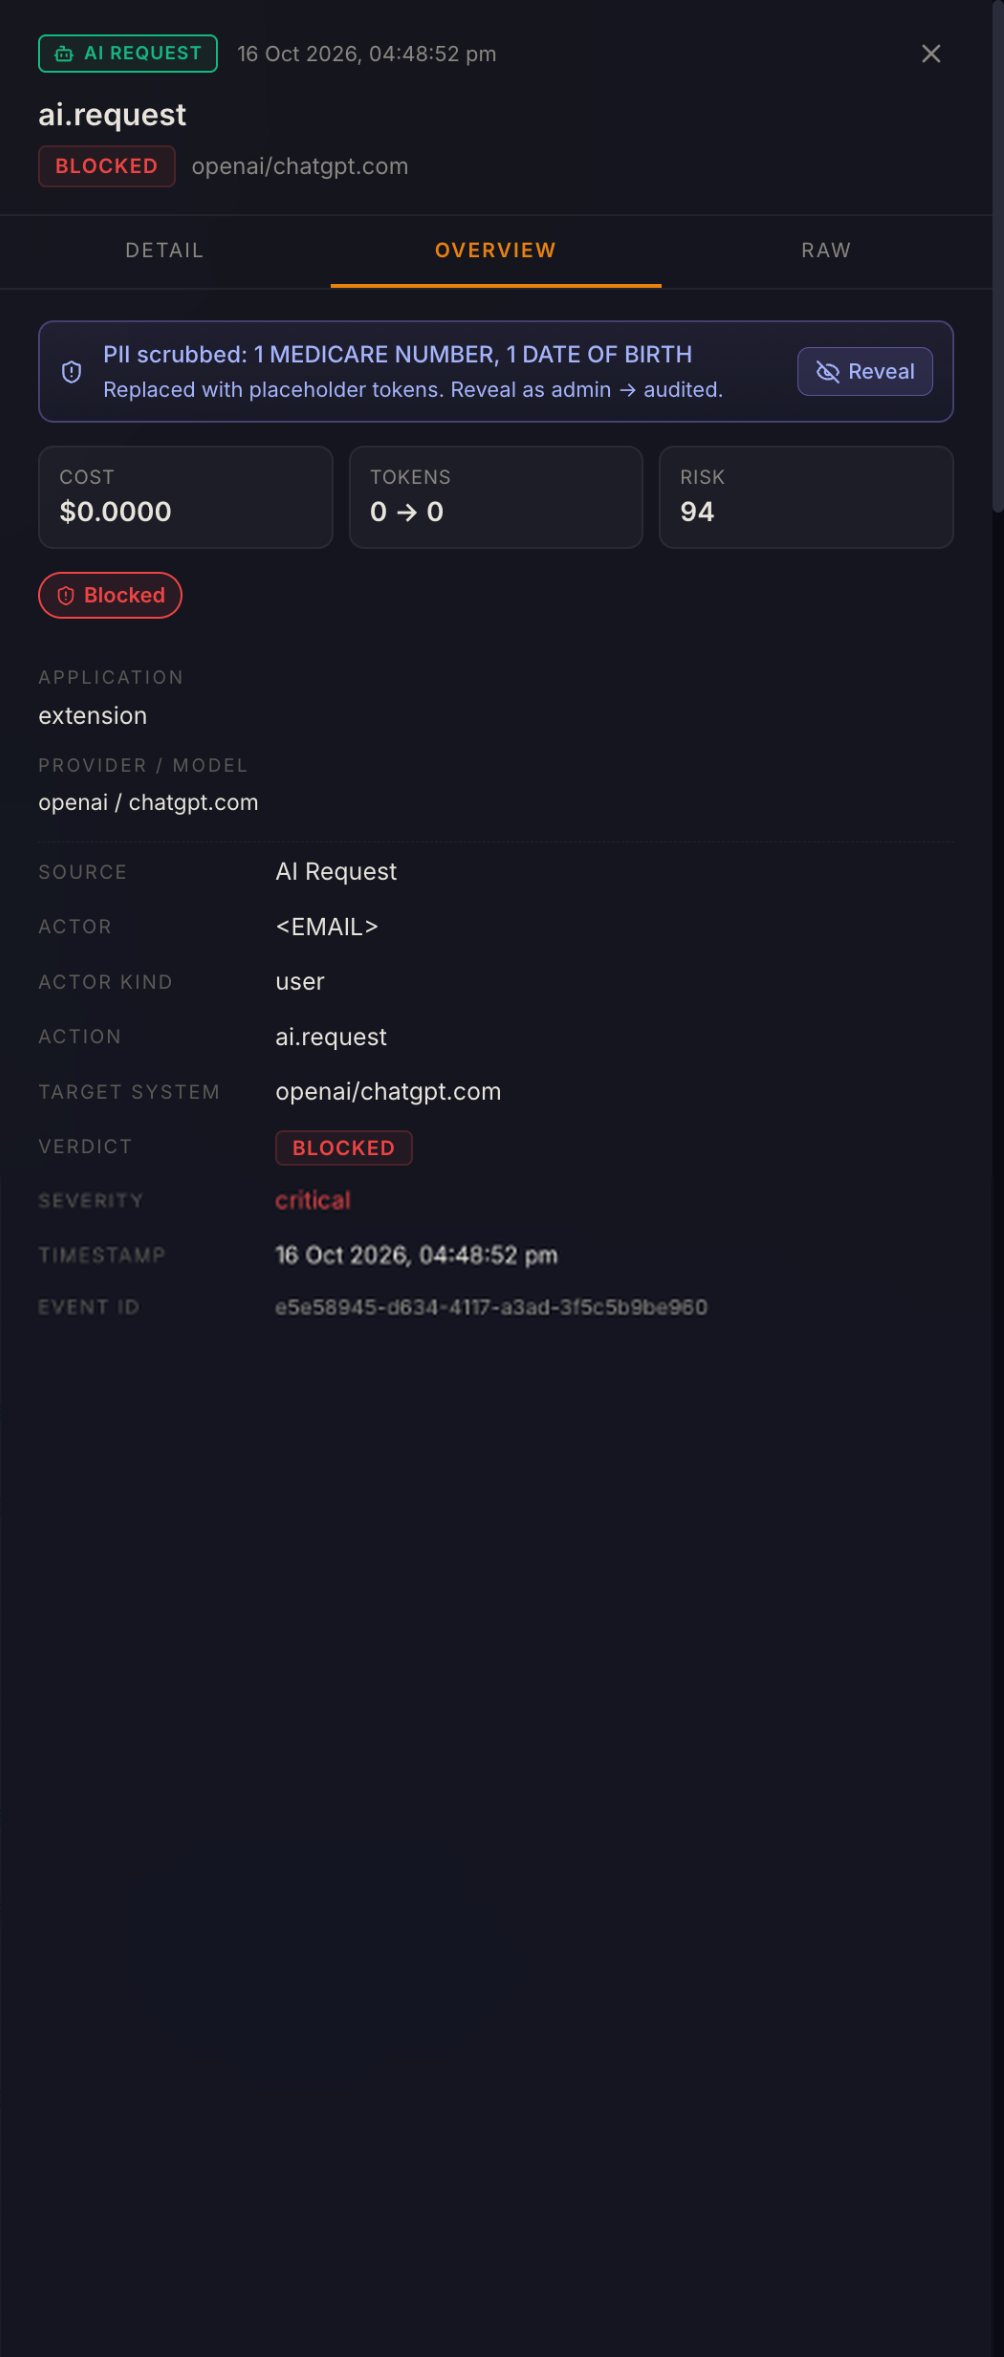
Click any call. See the kill chain.
Every OpenAI call is a row in Logs. Open one and Kapālins shows who called, what was inspected, which guardrail decided and why, before OpenAI ever saw the prompt, with the caller’s recent history beside it.
- Keep only a SHA-256 hash, or a scrubbed preview with identifiers replaced
- Mark a detection right or a false positive from the same panel
- The same record feeds incidents, your SIEM and the evidence pack
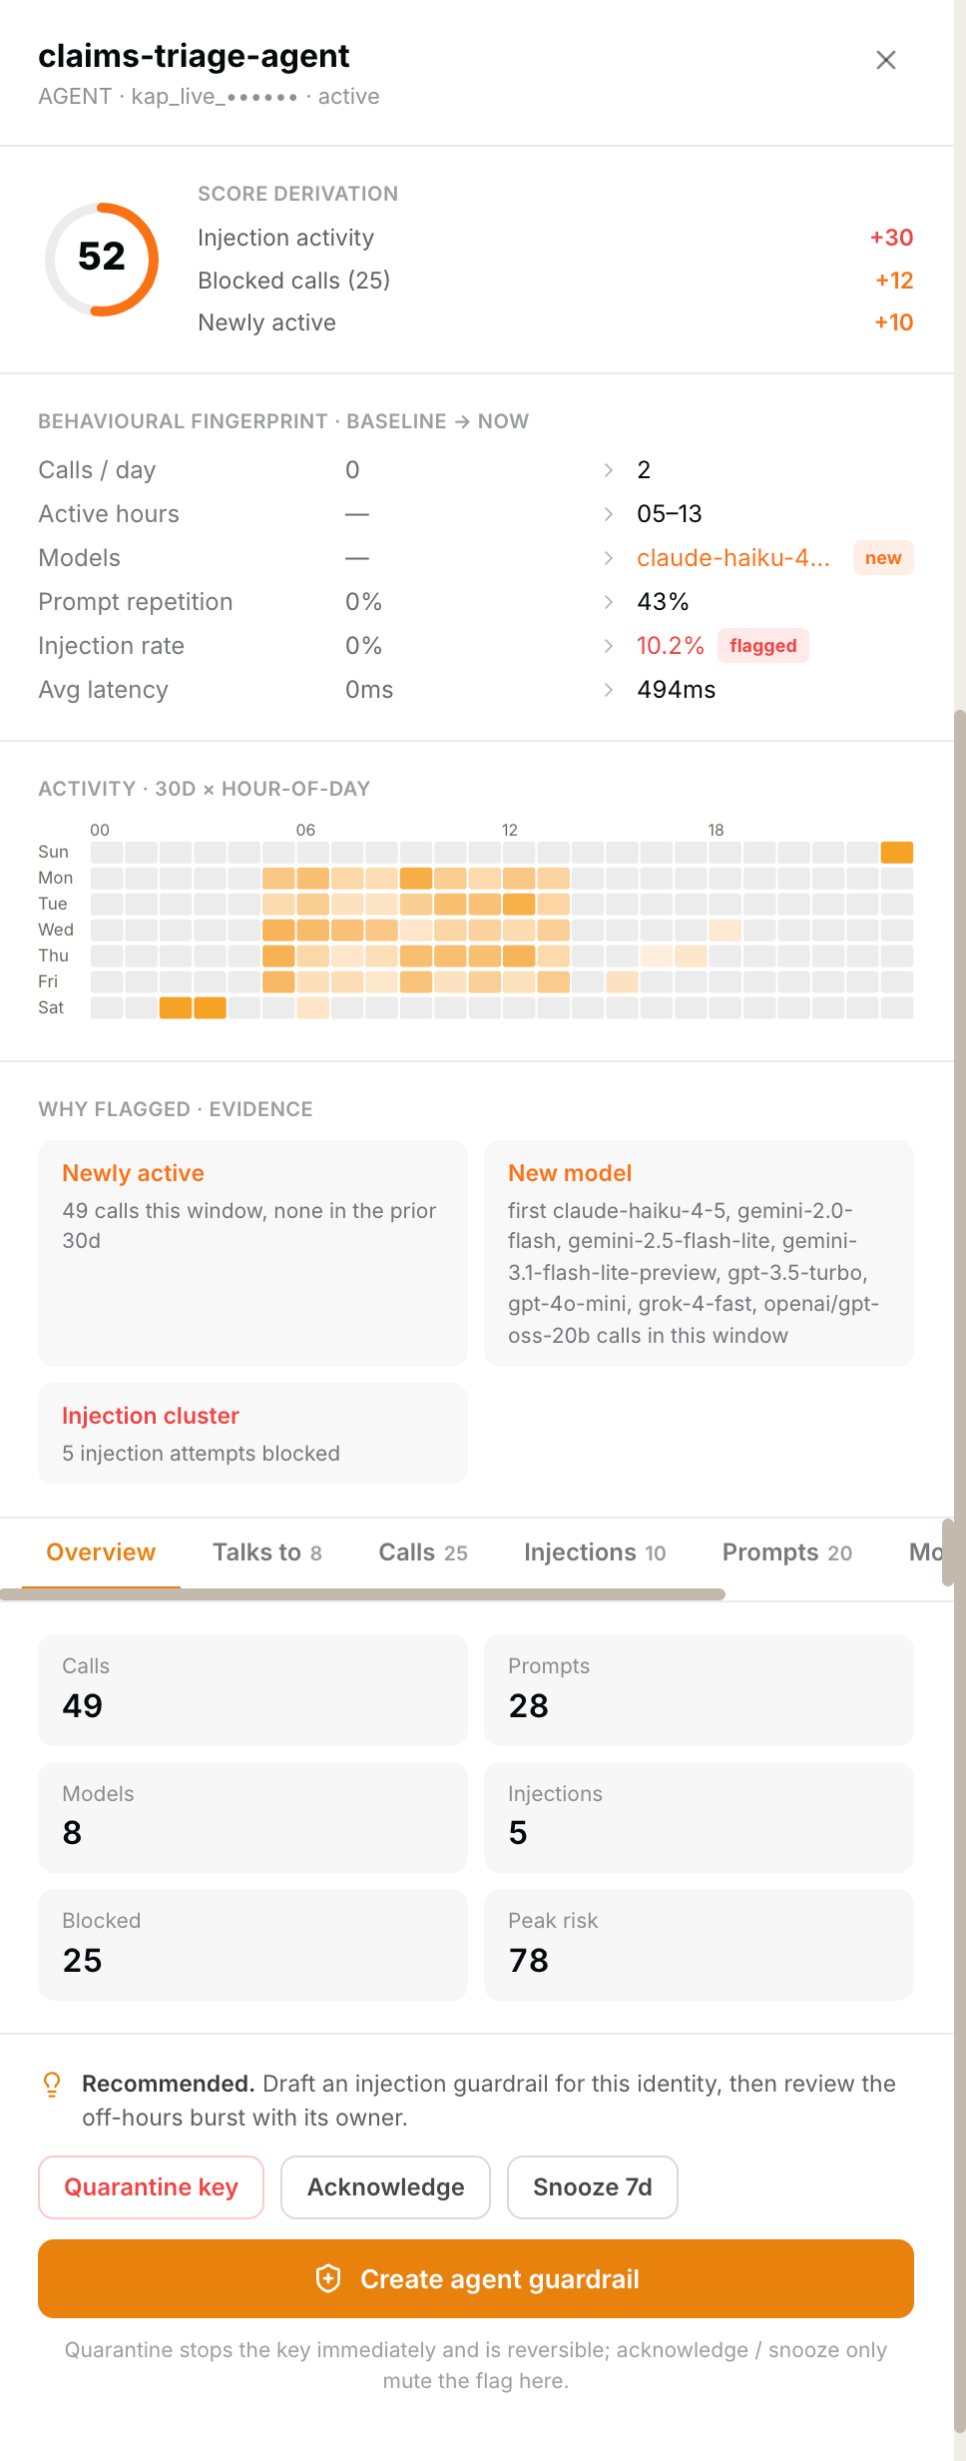
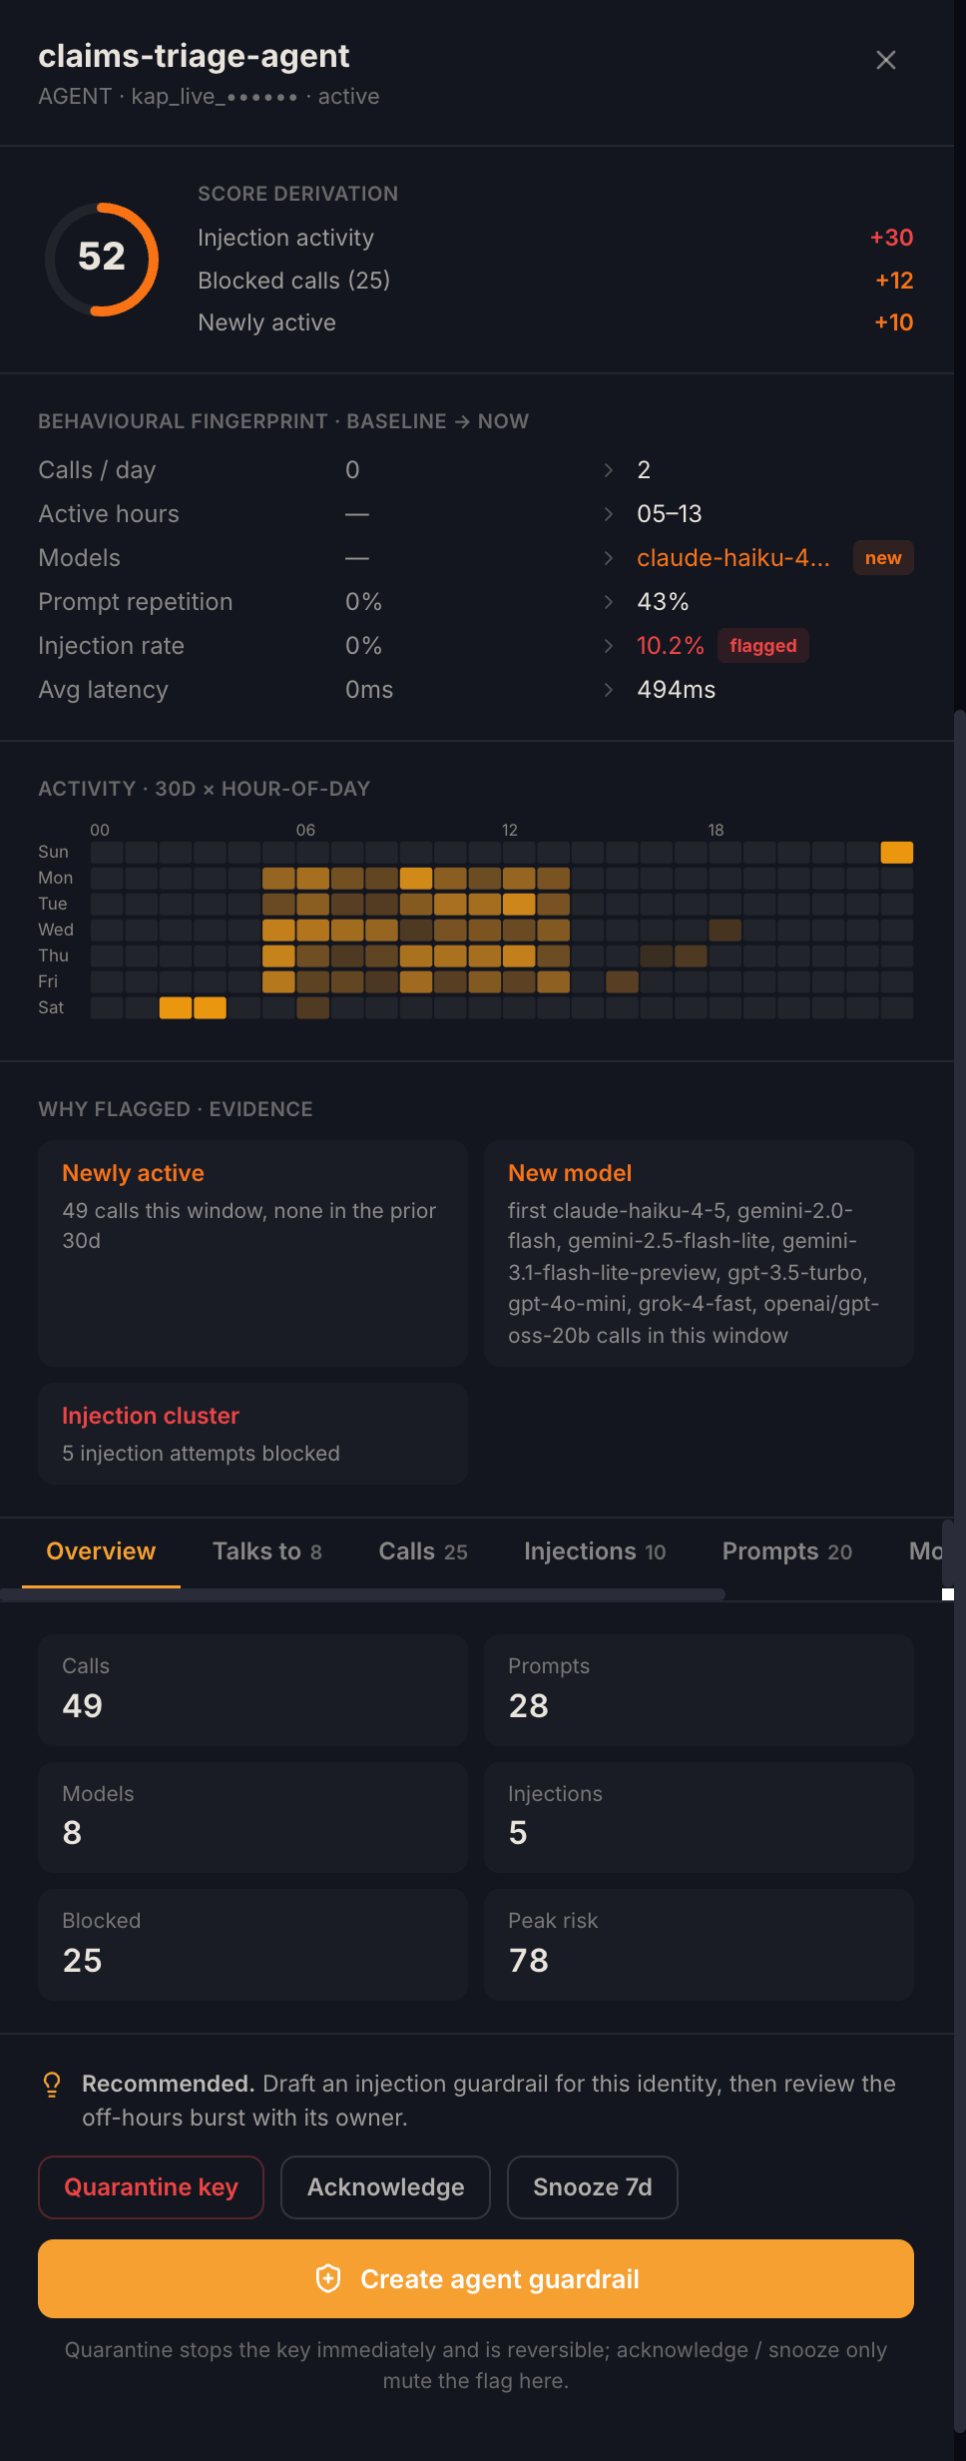
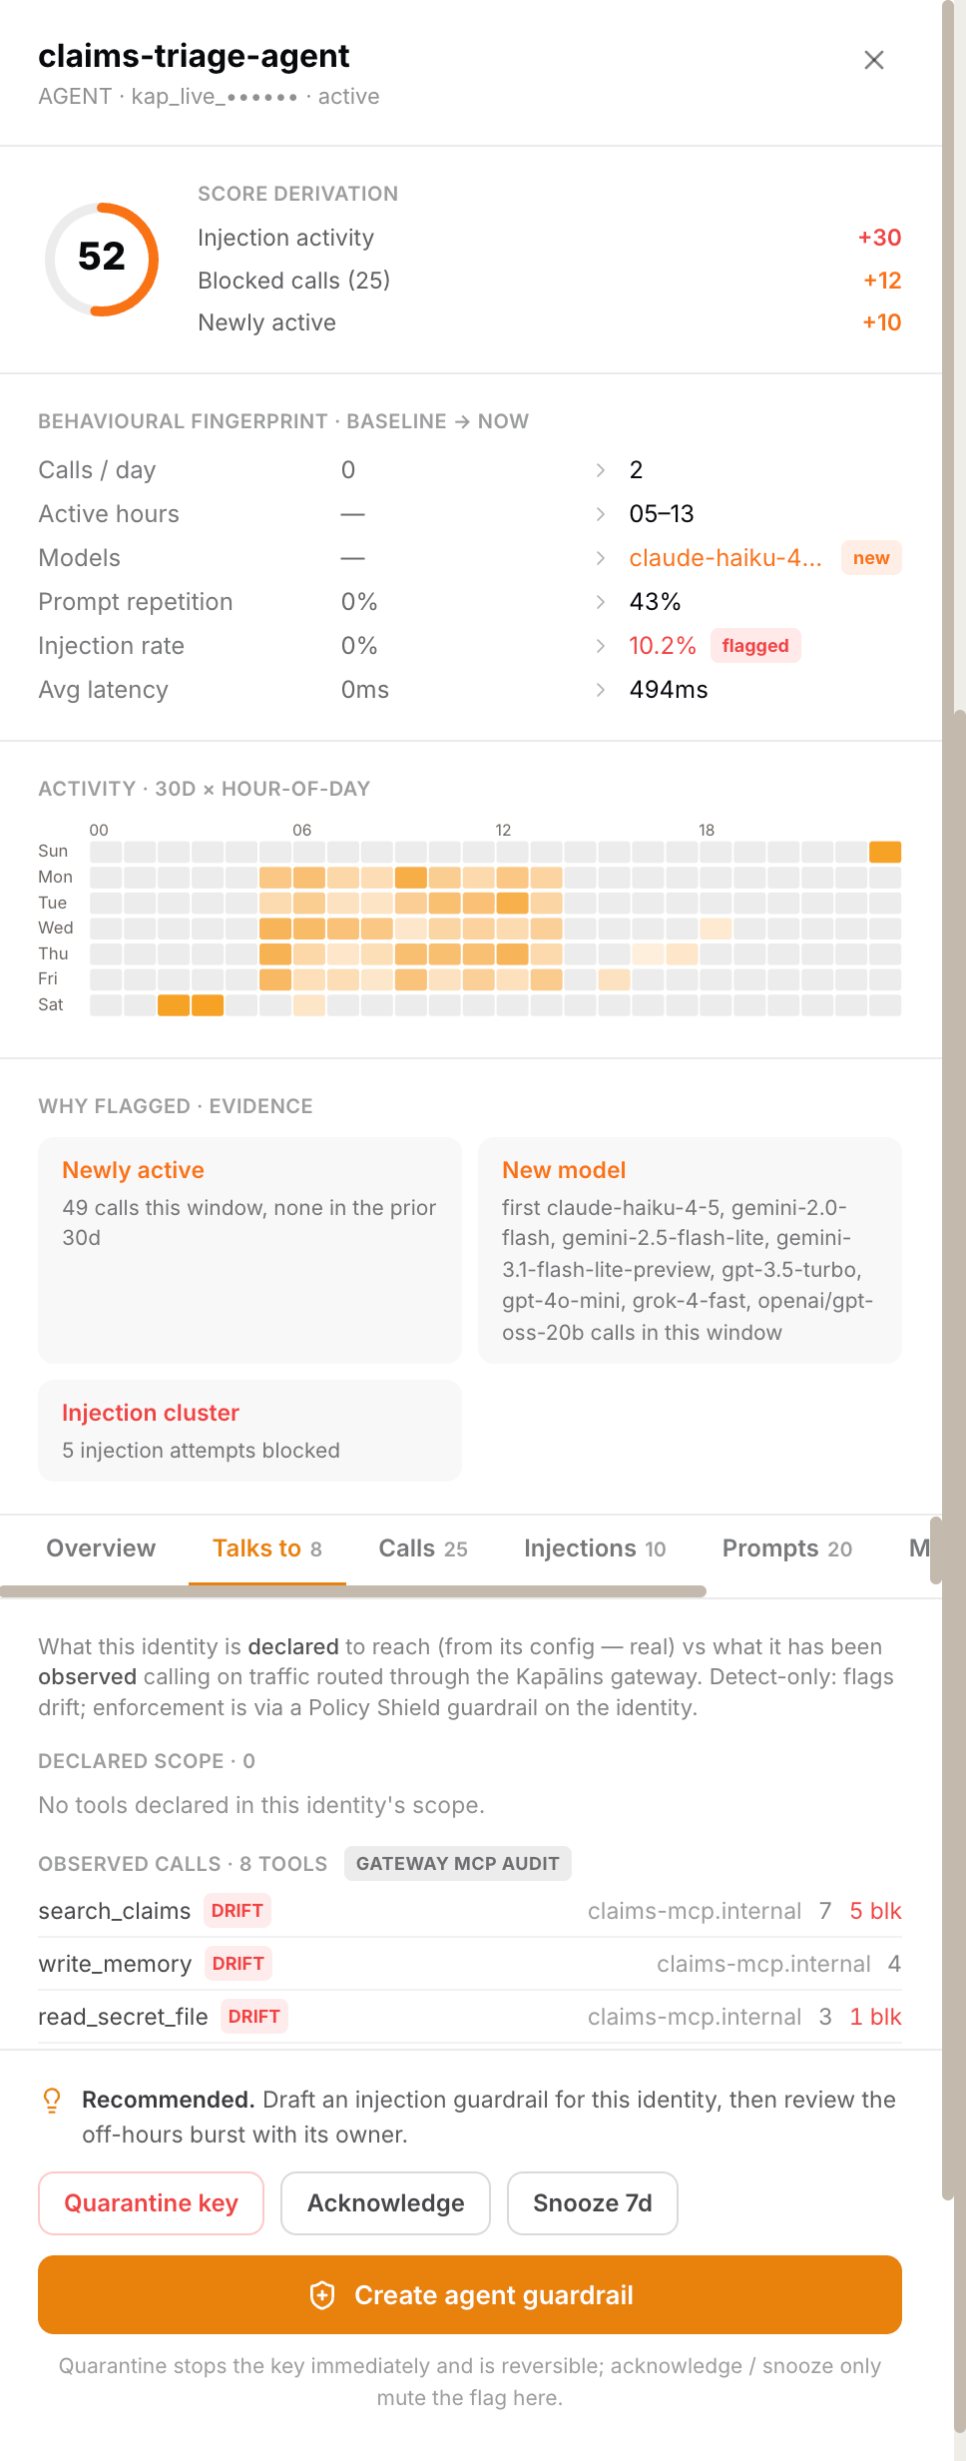
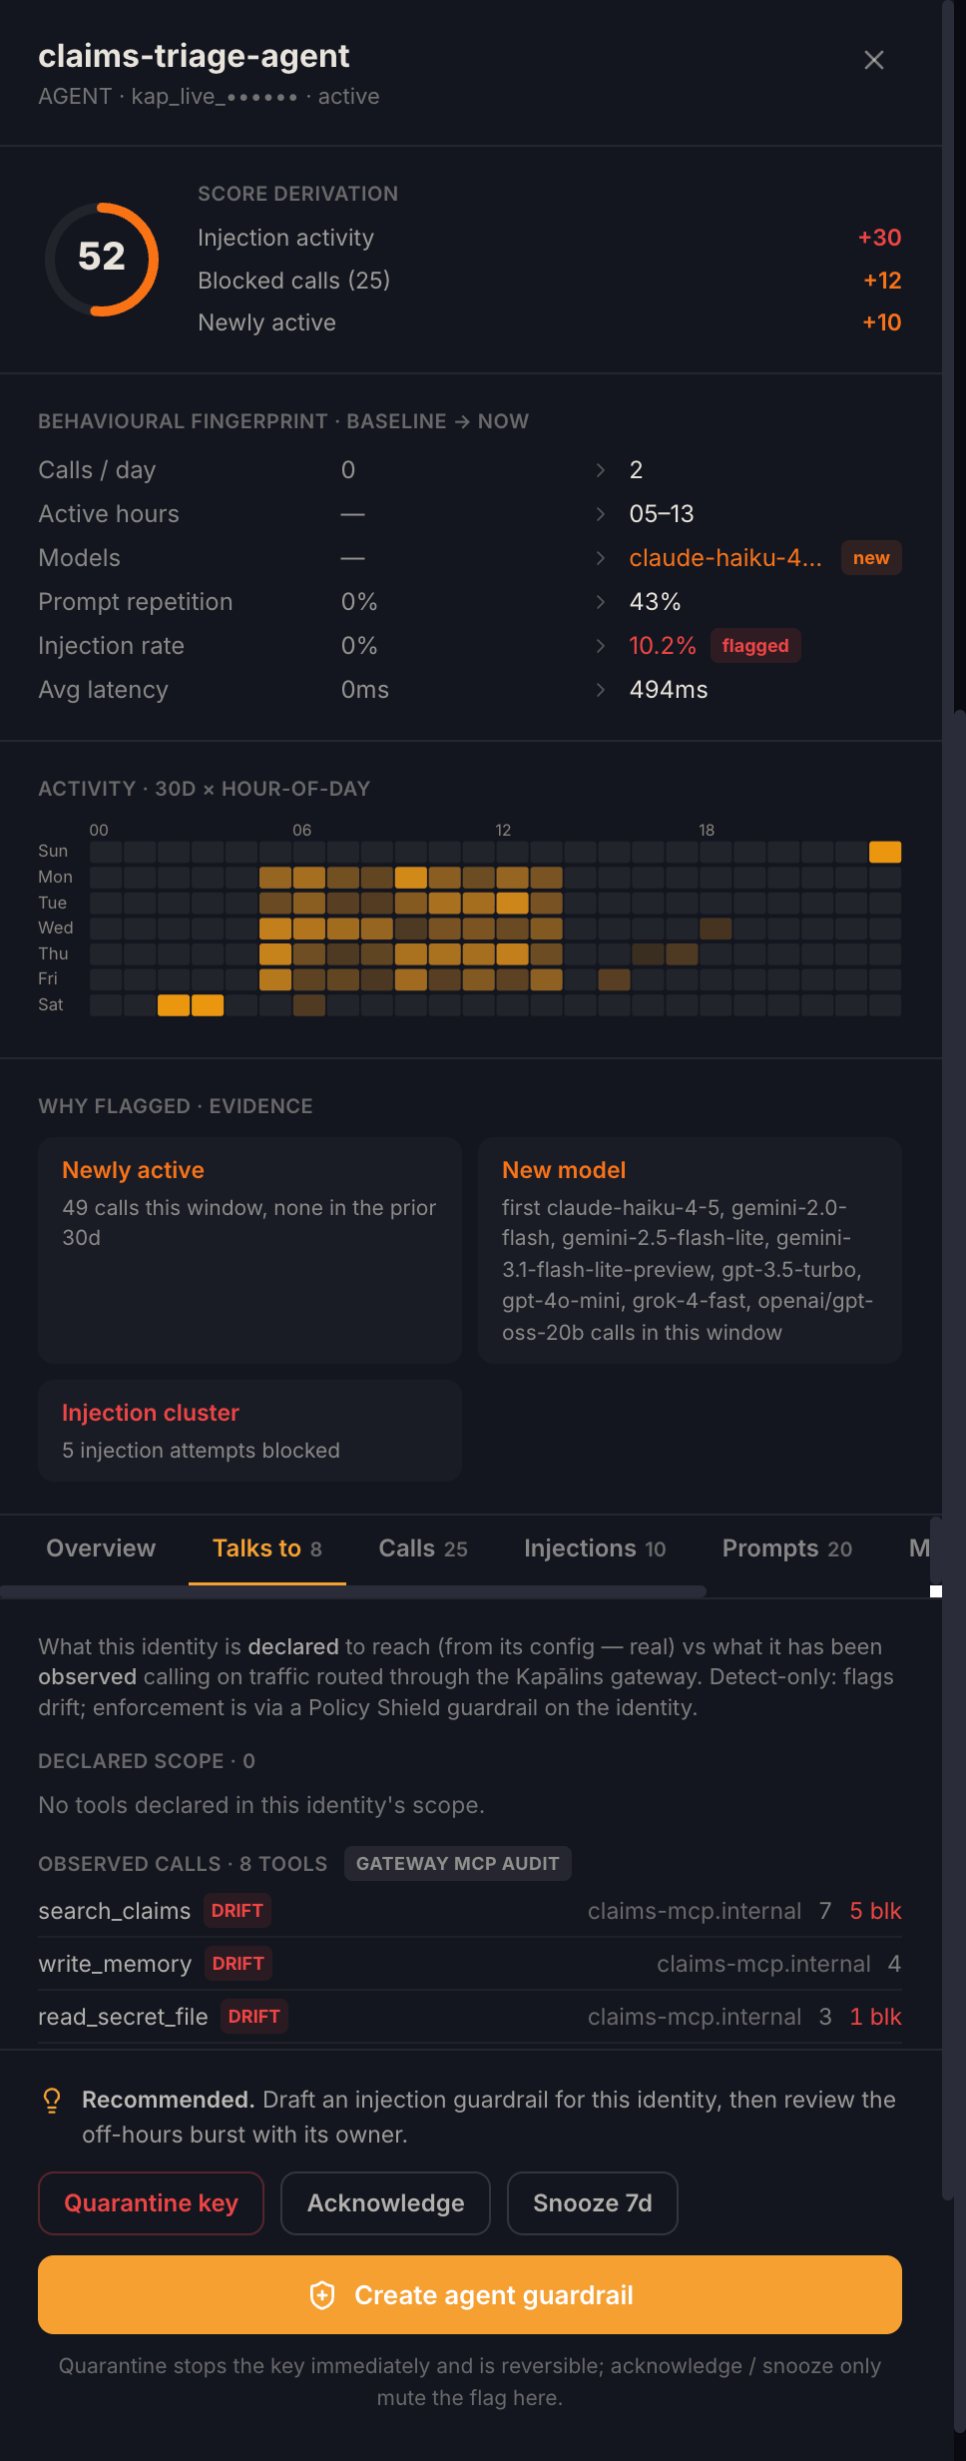
Agents calling OpenAI, fingerprinted.
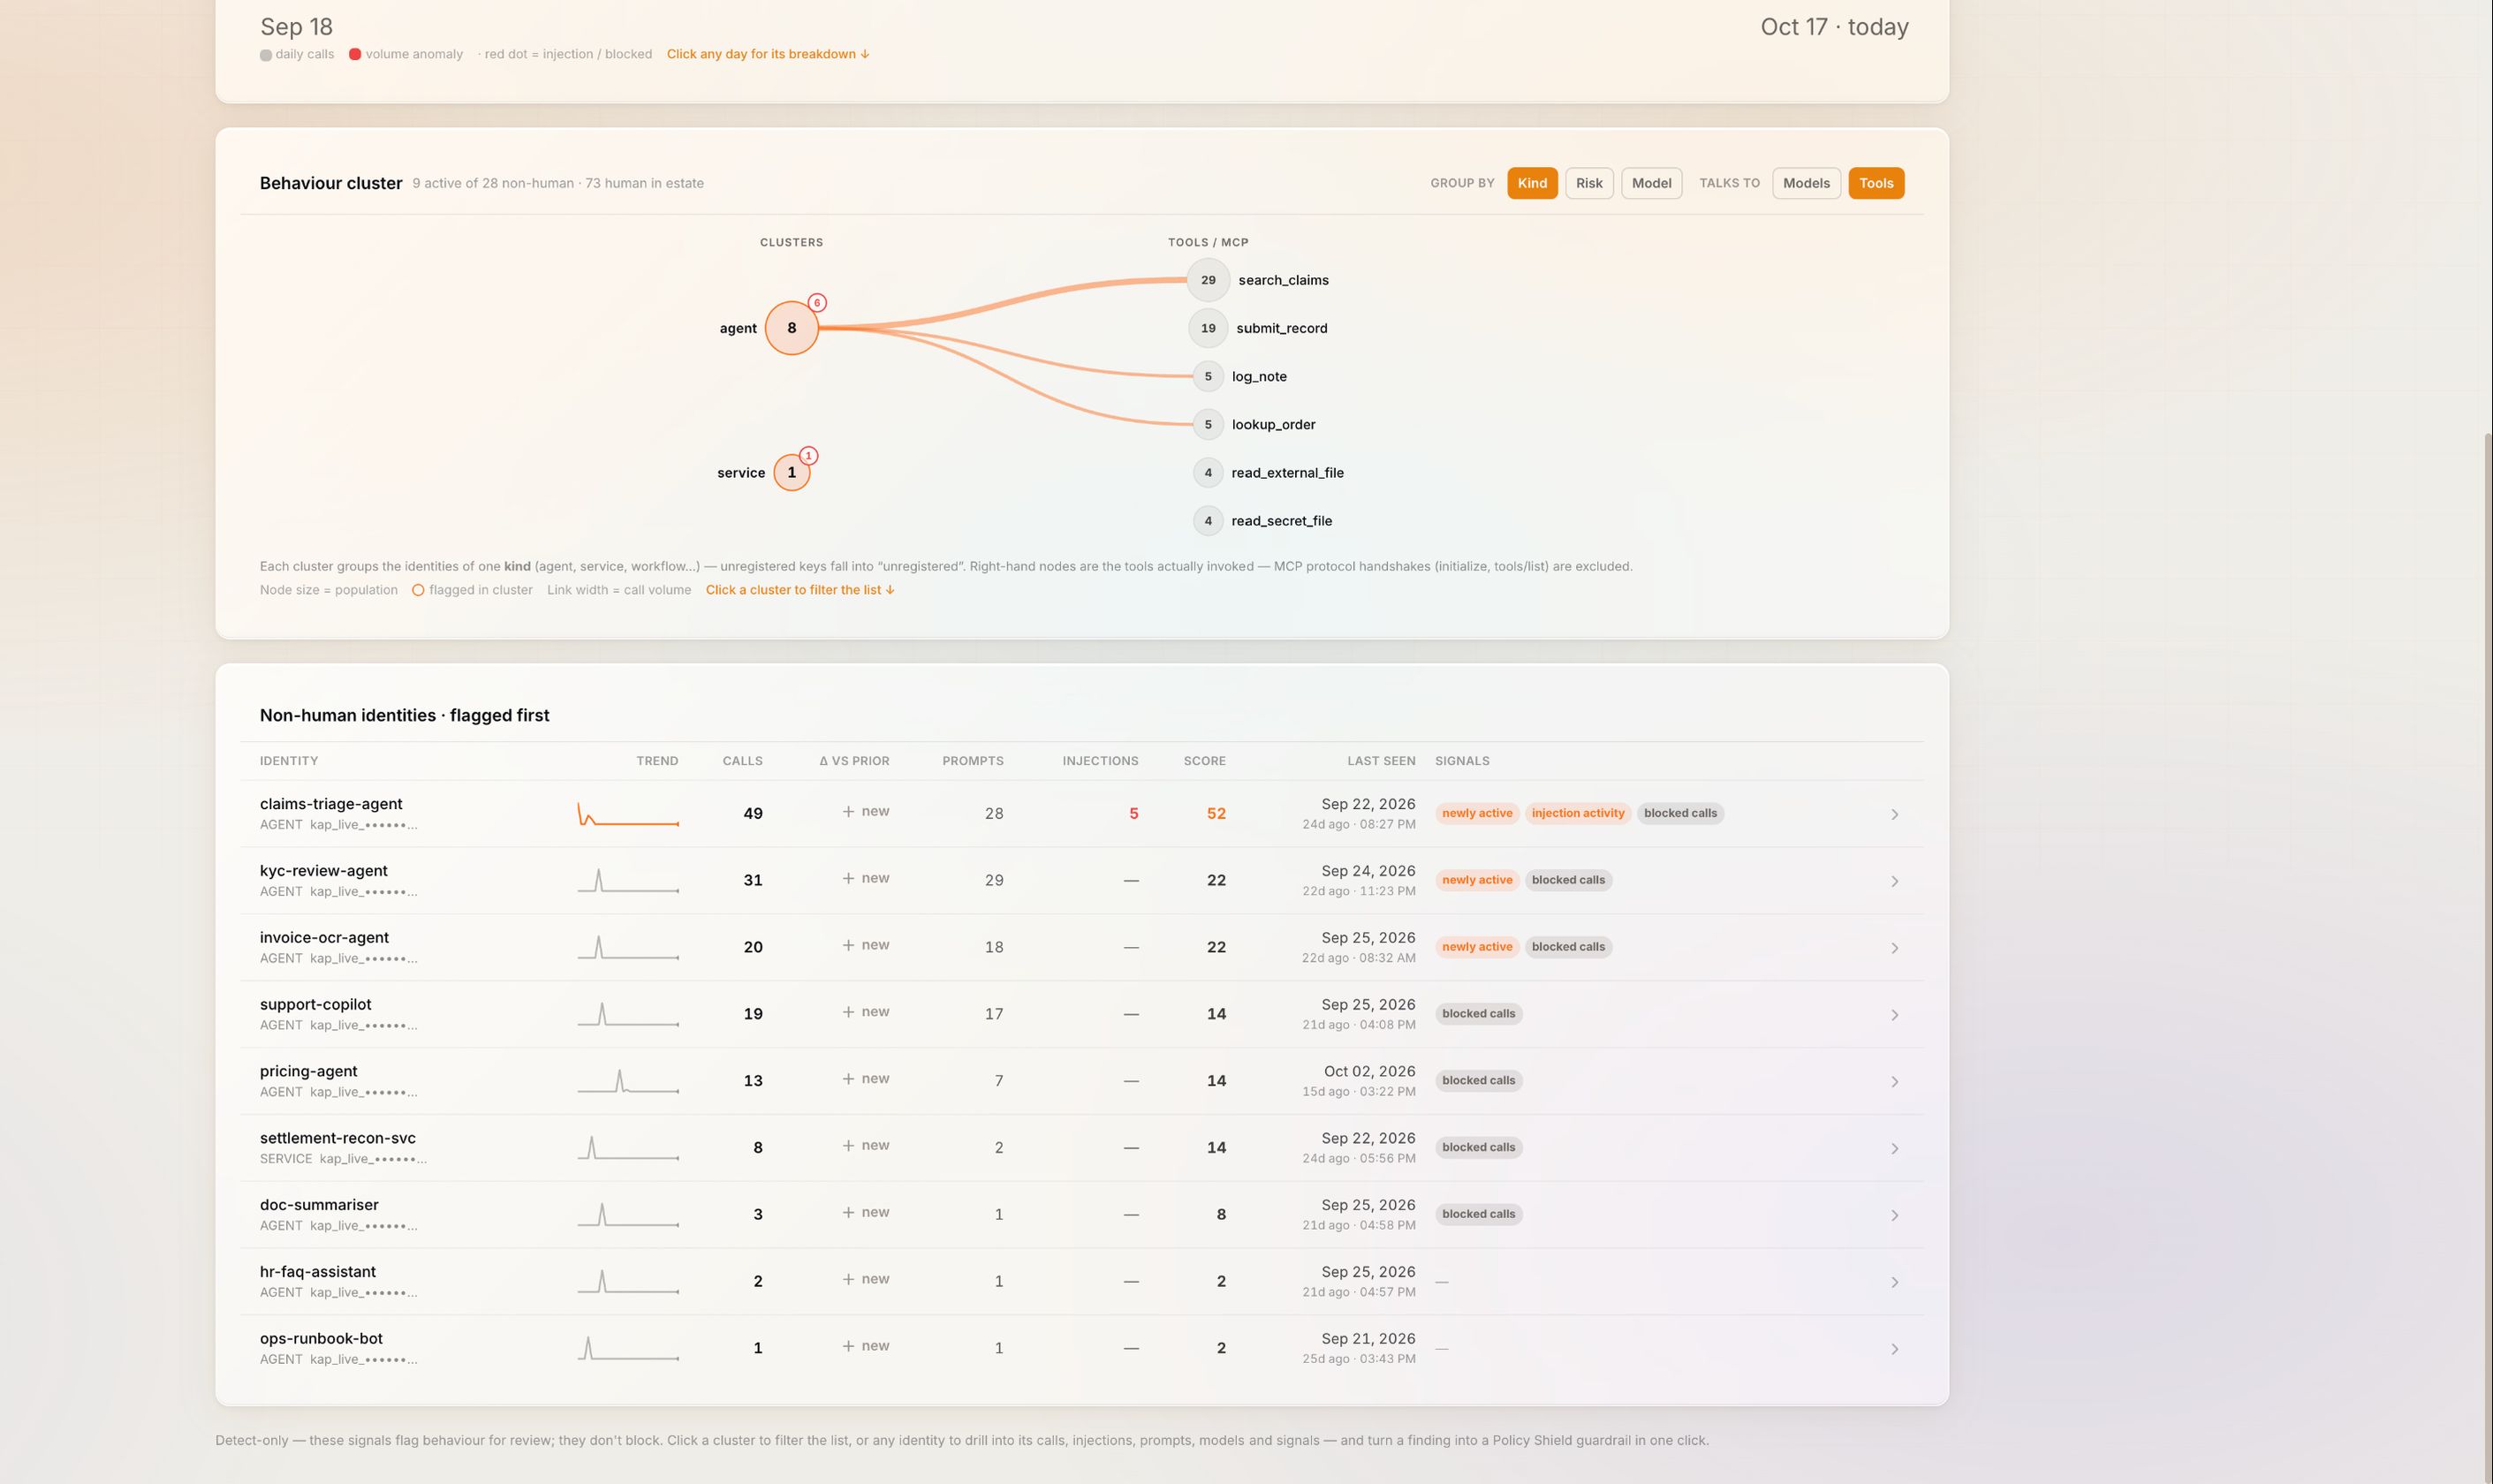
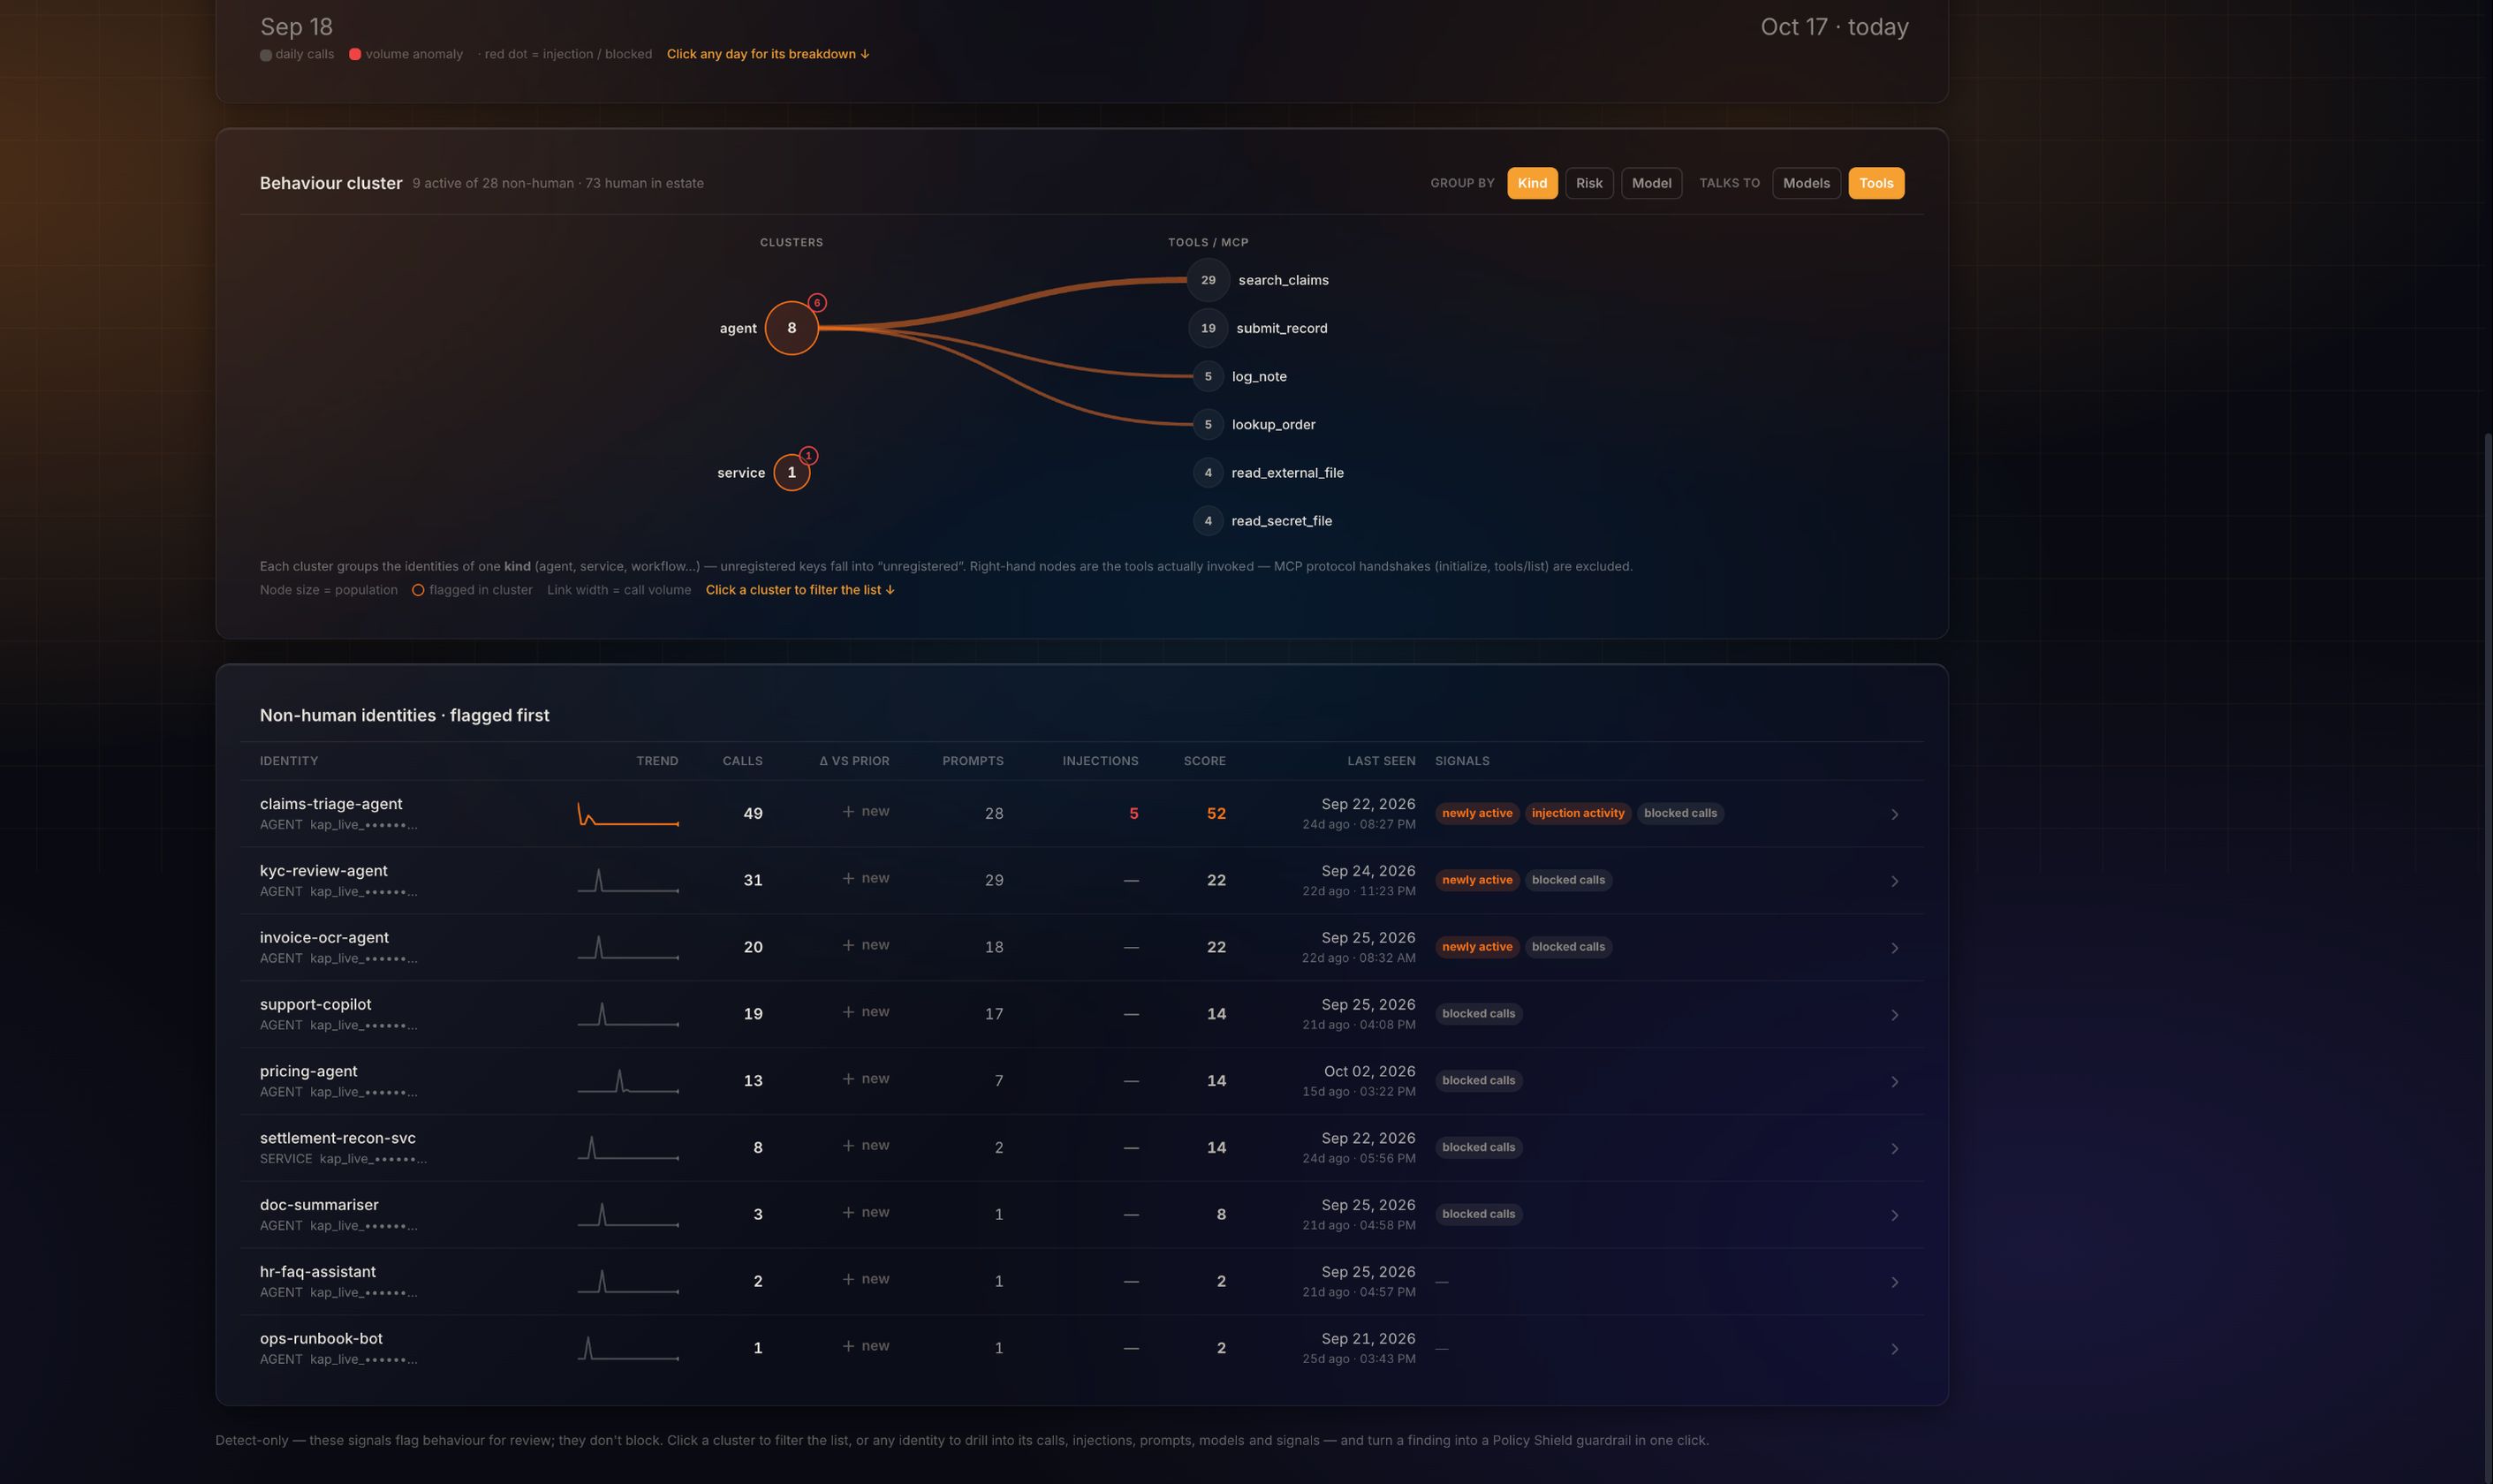
Every agent and service key that calls OpenAI through the gateway gets a behaviour baseline: calls, active hours, models, prompt repetition, injection rate. When one drifts it is flagged with the reasons, and one click drafts a guardrail or quarantines the key.
- The tools and MCP servers each agent actually invoked
- Detect only by default; quarantine is one click and reversible
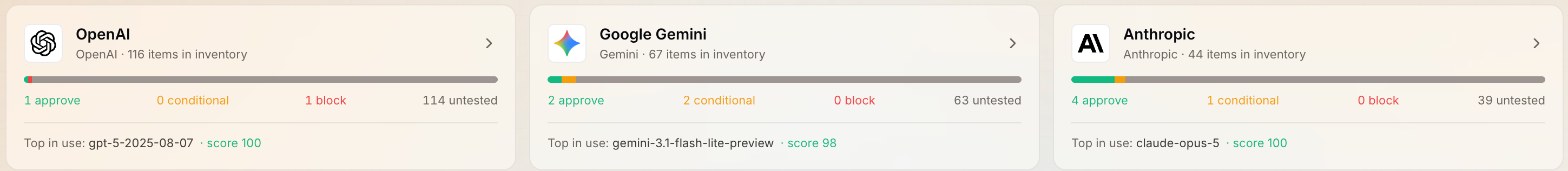
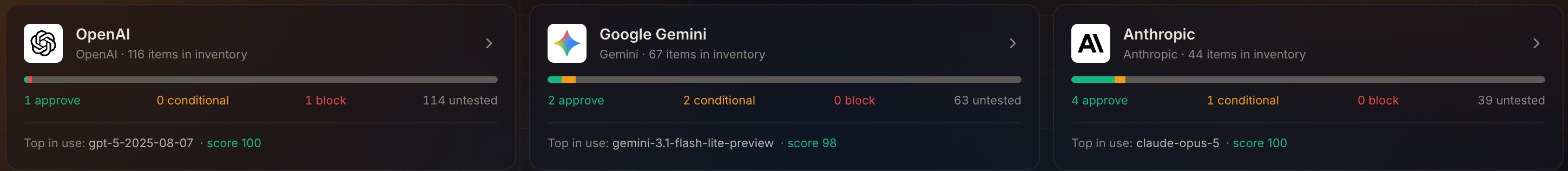
Every OpenAI model, approved or not.
The Probe Runner, the garak red team and Alignment Lab test each model you use, through your own key. A model is approved, conditional or blocked, and Policy Shield enforces the verdict at the gateway.
- Injection, unsafe code, harmful behaviour and hallucination suites
- A critical finding holds new use until someone approves it
Four steps.
- Add the providerIntegrations › OpenAI › paste the key. Kapālins checks it with a live call, then seals it.
- Issue virtual keysOne per application or agent, each with its own policy, models and budget.
- Change the base URLPoint the application at the gateway. Request and reply formats stay as they are.
- Detect, then enforceEvery shield starts in detect, so nobody is blocked on day one.
See OpenAI governed in thirty minutes.
Bring the person who holds the credential. We connect it live and watch the first events land.
Questions buyers ask.
Does the gateway add latency to OpenAI calls?
Policy Shield runs in the request path. Each family can be set to detect only, and the gateway reports its own added time per call in the timeline.
Do my applications need code changes?
A base URL and a key. The gateway accepts the OpenAI and Anthropic formats, so request and response handling stay as they are.
Can OpenAI be governed without the gateway?
Routing is what makes inline control possible. AI that cannot be routed, such as hosted copilots, is governed from its audit logs, identity grants and the device sensor instead.